How can Cache.match() reuse an app shell when URL search params change?
Match an offline app shell across harmless query-string changes with Cache.match(request, { ignoreSearch: true }), while keeping API and query-driven content exact so the wrong cached response never replaces live data.
A service worker cache can make an app feel solid offline, but it only helps when the request you look up is the request you meant to serve. That is easy when the URL is stable. It becomes trickier when the same app shell is reachable through several URLs that differ only by tracking parameters, marketing tags, or other harmless search text.
The useful distinction is not “cached versus uncached.” It is “same shell, different key” versus “different content, different key.” The first case wants a cache lookup that ignores the query string. The second case does not. If you apply the same rule everywhere, you can accidentally reuse a shell for data that should remain exact, or return one user’s cached response for another user’s query.
This article keeps the policy narrow: one chosen app-shell route may ignore search parameters, while API-style or query-driven requests keep exact matching. The example uses a small fetch handler and a controlled fixture so the difference is visible in the request path the handler chooses, not just in a hand-waved explanation.
One offline shell, two kinds of URLs
A service worker cache can make an app feel solid offline, but it only helps when the request you look up is the request you meant to serve. That is easy when the URL is stable. It becomes trickier when the same app shell is reachable through several URLs that differ only by tracking parameters, marketing tags, or other harmless search text.
The useful distinction is not “cached versus uncached.” It is “same shell, different key” versus “different content, different key.” The first case wants a cache lookup that ignores the query string. The second case does not. If you apply the same rule everywhere, you can accidentally reuse a shell for data that should remain exact, or return one user’s cached response for another user’s query.
This article keeps the policy narrow: one chosen app-shell route may ignore search parameters, while API-style or query-driven requests keep exact matching. The example uses a small fetch handler and a controlled fixture so the difference is visible in the request path the handler chooses, not just in a hand-waved explanation.
- Use `ignoreSearch: true` only for the one route whose search parameters do not change the shell.
- Leave API requests and search-driven content on exact matching so the query remains part of the cache key.
- Treat the service worker as the place where you choose cache policy, not as a blanket offline switch.
// This module contains no service-worker side effects on import.
// Proof boundary: the route selection below is application code. A real browser
// service worker is still required to prove Cache.match()'s own cache semantics.

export const APP_SHELL_PATH = "/app";

export function isAppShellRequest(request) {
  const url = new URL(request.url);
  return request.method === "GET" && url.pathname === APP_SHELL_PATH;
}

/**
 * Handles an already-intercepted service-worker fetch request.
 *
 * Only GET requests are eligible for cache lookup. Within that set, only the
 * chosen app-shell route ignores its query string; API endpoints and other
 * query-driven routes use Cache.match()'s default exact matching.
 */
export async function handleAppShellFetch(request, { cache, networkFetch }) {
  // Cache.match() normally only matches GET and HEAD requests, but this policy
  // intentionally does not involve the cache for any non-GET operation.
  if (request.method !== "GET") {
    return networkFetch(request);
  }

  const cached = isAppShellRequest(request)
    ? await cache.match(request, { ignoreSearch: true })
    : await cache.match(request);

  return cached ?? networkFetch(request);
}

/**
 * Optional service-worker wiring. Call this from the service-worker script
 * after opening the intended Cache instance.
 */
export function registerAppShellFetchHandler(scope, dependencies) {
  scope.addEventListener("fetch", (event) => {
    event.respondWith(handleAppShellFetch(event.request, dependencies));
  });
}
SourcesMDN: Cache.match() (opens a new tab)MDN: Using Service Workers (opens a new tab)
Start with the route, not the cache
The first mistake in cache handling is to think the cache itself should decide what kind of request it is. In practice, the application owns that decision. A service worker can only apply a lookup policy after your code has identified the request as something that should be served from a cache at all.
The example uses a small predicate: only `GET` requests to `/app` qualify for app-shell reuse. That keeps navigation-like requests separate from API calls and form submissions. Once the request is inside that narrow lane, the handler can ask for `ignoreSearch: true` because the path is the same app shell whether the browser arrived at `/app?utm_source=newsletter` or `/app?theme=dark`. The query string does not change the shell document; it only changes how the browser reached it.
This is where many articles get too broad. A service worker is not a general excuse to ignore query strings. It is a place to encode a very specific rule: when the path identifies the shell and the search string is incidental, ignore it. When the search string selects actual content, keep it in the key and leave the request exact.
- The route decision happens before the cache lookup.
- `ignoreSearch` changes how the cache key is compared, not what the app thinks the URL means.
- A GET-only check prevents non-idempotent requests from being treated like shell navigation.
SourcesMDN: Cache.match() (opens a new tab)MDN: Using Service Workers (opens a new tab)
Let one shell answer multiple navigation URLs
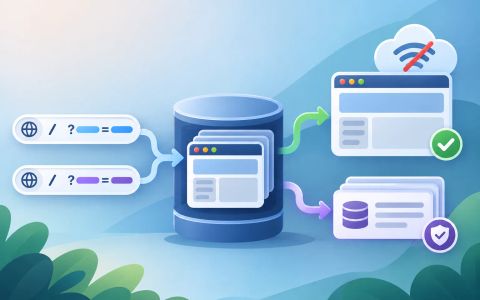
The core of the repair is tiny. For the app-shell route, call `cache.match(request, { ignoreSearch: true })`. If the cache contains a response for `/app`, that response can satisfy `/app?utm_source=newsletter` and `/app?theme=dark` because the query string is no longer part of the cache comparison. The lookup is still path-aware; it does not turn every URL into the same key.
That distinction matters because the app shell is usually a document or bootstrap asset, not a data result. When the shell loads, client-side code can read the current URL and decide what state to render. The shell itself does not need a separate cached copy for each campaign parameter or cosmetic query flag. Caching those variants separately wastes space and makes offline behavior harder to reason about.
The effect is easy to describe but important to keep precise: the browser still requests different URLs, and your handler still receives the full `Request`. Only the cache lookup ignores the search string. That means the policy is local and explicit rather than magical. If you later decide that a second route should also ignore search, you add it on purpose instead of broadening the rule for the entire service worker.
- `cache.match(request, { ignoreSearch: true })` matches on path while discarding the query string.
- The same cached shell can satisfy two URLs that differ only by search text.
- The search string still exists on the `Request`; only the comparison changes.
Keep data-bearing requests exact
The reason not to use `ignoreSearch` everywhere is that query parameters often are the data. A profile endpoint may use `?user=bob`, a search endpoint may use `?q=shoes`, and a report page may use `?month=2026-11`. Those values are not decoration. They change the meaning of the response. If you discard them during matching, the cache can no longer distinguish one request from another.
That is why the handler in the example leaves API and query-driven requests on the default `cache.match(request)` path. The cache lookup stays exact, so `/api/profile?user=bob` will not accidentally match `/api/profile?user=alice`. This is not merely a performance concern. It is a correctness boundary. A fast but wrong cached response is worse than a slower network response when the data belongs to a different user or a different query.
The point of the control case is to show that `ignoreSearch` is a selective tool, not a general optimization. The app-shell route can ignore tracking parameters because the shell’s identity is tied to its path. A search endpoint cannot do that because the search string is the identity. Those are different contracts, so they need different matching rules.
- Exact matching keeps the query string as part of the identity.
- This avoids mixing content that is keyed by user, filter, locale, or sort order.
- A cache hit is only useful if the response still belongs to the request.
The fetch handler stays small on purpose
The handler in the article is deliberately boring, which is a compliment. It accepts a request, checks whether the request belongs to the chosen shell route, and asks the cache with the right matching rule. If a cached response exists, it returns that response. If not, it falls through to the network fetch function. That is enough structure to make the policy visible without hiding it in a framework abstraction.
There is one more useful detail: the `registerAppShellFetchHandler()` wrapper is separate from the policy function. That makes the request decision testable without requiring a full service-worker runtime in every unit test. The application logic can be checked in Node, while the browser-specific integration still happens inside a real worker when you wire it into your site. This separation keeps the example honest about what each test layer proves.
The same shape also makes the failure boundary easy to state. If the cache has no shell entry, the app still works from the network. If the request is not the shell route, the cache is not asked to ignore the search string. If the request is a non-GET request, the handler bypasses the cache entirely. Each branch has a different purpose, and none of them need a larger abstraction to exist.
- The handler can fall through to the network when the cache has no suitable response.
- `Cache.match()` returns a `Response` or `undefined`; the code decides what to do next.
- A service worker should not intercept requests it does not understand.
SourcesMDN: Using Service Workers (opens a new tab)MDN: Cache.match() (opens a new tab)
What the tests can prove, and what they cannot
The Node fixture in the example proves the application policy, not the browser implementation of `Cache.match()` itself. That distinction matters. The tests can verify that the handler asks for `ignoreSearch: true` only on the shell route and that exact matching is preserved for API-style requests. They can also prove that a non-GET request bypasses the cache. Those are the decisions your code owns.
What the tests do not prove is the browser’s own cache engine, its secure-context requirements, or the full service-worker lifecycle. Those remain browser behavior, which is why the article treats the browser service worker as the integration step and the Node tests as the policy step. The distinction is useful because the application can be correct in structure even when the browser layer still needs manual verification in a secure origin.
This is also why the wrong fix is so tempting. If you only test a single successful app-shell hit, it is easy to conclude that `ignoreSearch` is simply a performance trick. The failure case shows why that is incomplete. The same lookup option that solves one navigation problem becomes unsafe when the query string carries actual data. The right answer is not to avoid `ignoreSearch`; it is to confine it to the route that can safely use it.
- A controlled fixture should show the same shell response for two URLs with different search text.
- A second fixture should show the handler refusing to blur a data request.
- A non-GET request proves the route guard is part of the policy, not an accident.
import test from "node:test";
import assert from "node:assert/strict";
import { handleAppShellFetch } from "./main.mjs";

// These Node tests verify this application's routing policy and its calls to
// Cache.match(). They do not prove browser Cache API matching; run the same
// handler in a secure-context service worker for that integration proof.

test("app-shell URLs with different tracking searches use ignoreSearch cache matching", async () => {
  const calls = [];
  const cache = {
    async match(request, options) {
      calls.push({ url: request.url, options });
      if (options?.ignoreSearch && new URL(request.url).pathname === "/app") {
        return new Response("offline app shell");
      }
      return undefined;
    },
  };
  const networkFetch = async () => {
    throw new Error("the app shell should have been served from cache");
  };

  const campaignResponse = await handleAppShellFetch(
    new Request("https://example.test/app?utm_source=newsletter"),
    { cache, networkFetch },
  );
  const harmlessResponse = await handleAppShellFetch(
    new Request("https://example.test/app?theme=dark"),
    { cache, networkFetch },
  );

  assert.equal(await campaignResponse.text(), "offline app shell");
  assert.equal(await harmlessResponse.text(), "offline app shell");
  assert.deepEqual(calls.map((call) => call.options), [
    { ignoreSearch: true },
    { ignoreSearch: true },
  ]);
});

test("API requests keep their search parameters exact instead of returning another user's cached data", async () => {
  const calls = [];
  const cache = {
    async match(request, options) {
      calls.push({ url: request.url, options });
      // This represents a cached response for Alice only. The handler must not
      // ask this dependency to ignore the query and accidentally select it.
      if (request.url === "https://example.test/api/profile?user=alice") {
        return new Response('{"user":"alice"}');
      }
      return undefined;
    },
  };
  const networkFetch = async (request) => {
    assert.equal(request.url, "https://example.test/api/profile?user=bob");
    return new Response('{"user":"bob"}');
  };

  const response = await handleAppShellFetch(
    new Request("https://example.test/api/profile?user=bob"),
    { cache, networkFetch },
  );

  assert.equal(await response.text(), '{"user":"bob"}');
  assert.deepEqual(calls, [{
    url: "https://example.test/api/profile?user=bob",
    options: undefined,
  }]);
});

test("a non-GET request to the app-shell path bypasses the cache", async () => {
  let cacheWasCalled = false;
  const cache = {
    async match() {
      cacheWasCalled = true;
      return new Response("incorrect cached shell");
    },
  };
  const networkFetch = async (request) => {
    assert.equal(request.method, "POST");
    return new Response("network POST result", { status: 201 });
  };

  const response = await handleAppShellFetch(
    new Request("https://example.test/app?utm_source=newsletter", {
      method: "POST",
    }),
    { cache, networkFetch },
  );

  assert.equal(cacheWasCalled, false);
  assert.equal(response.status, 201);
  assert.equal(await response.text(), "network POST result");
});
A simple rule for the next cache you design
A practical rule emerges from the example: if the path identifies a reusable shell and the search string only reflects the way the user arrived there, `ignoreSearch` may be appropriate. If the search string changes the meaning of the response, keep exact matching. That single distinction is often enough to prevent the two most common mistakes: missing an offline shell because of harmless tracking text, and serving the wrong response because the query was discarded too aggressively.
There are still limits. `ignoreSearch` does not normalize path aliases, sort query parameters for you, or decide which routes deserve caching in the first place. It only changes the comparison rule for the URL search component during a cache match. That means you still need to decide which paths are canonical, which requests are safe to serve offline, and which data should always come from the network or from an exact cache key.
If the app shell is your only offline target, the narrow policy is usually enough. If the site has more complicated client routing, you can extend the same approach by naming the routes that may ignore search and leaving everything else exact. The key is to keep the rule visible in code. That way the next person who reads the service worker can tell, at a glance, which URLs are intentionally interchangeable and which ones are not.
- Choose `ignoreSearch` for canonical shell URLs, not for every cached request.
- Leave query-sensitive routes exact, even if they are often offline-cached too.
- The useful limit is simple: if the search string changes the meaning, do not ignore it.
SourcesMDN: Using Service Workers (opens a new tab)MDN: Cache.match() (opens a new tab)