When should an AI model propose a tool call versus when the app executes it?
A practical boundary for OpenAI function calling: the model proposes a tool call, the app validates and executes it, and UI commit happens only after a verified action. A small in-memory fixture shows the contract without external dependencies.
Function calling is easiest to misuse when the model is treated as if it were already authorized to do the work. The important boundary is not just whether the tool schema is valid; it is whether the application accepts the proposal, executes the side effect, and only then commits the result to the user-facing state. That boundary matters because a malformed proposal, an out-of-scope request, or a cancelled action should fail before the UI changes, not after it has already shown a result that cannot be trusted.
This article uses one small in-memory fixture to show the separation end to end. The model side is represented by a proposed JSON tool call, the application side validates the name and arguments, the tool implementation either returns a result or signals cancellation, and a commit callback updates the view only after the result is known. The same fixture also demonstrates what the pattern does not solve: it does not replace server authorization, it does not guarantee that the model chose the right tool, and it does not make every schema design safe by itself.
Start with the boundary the UI can actually enforce
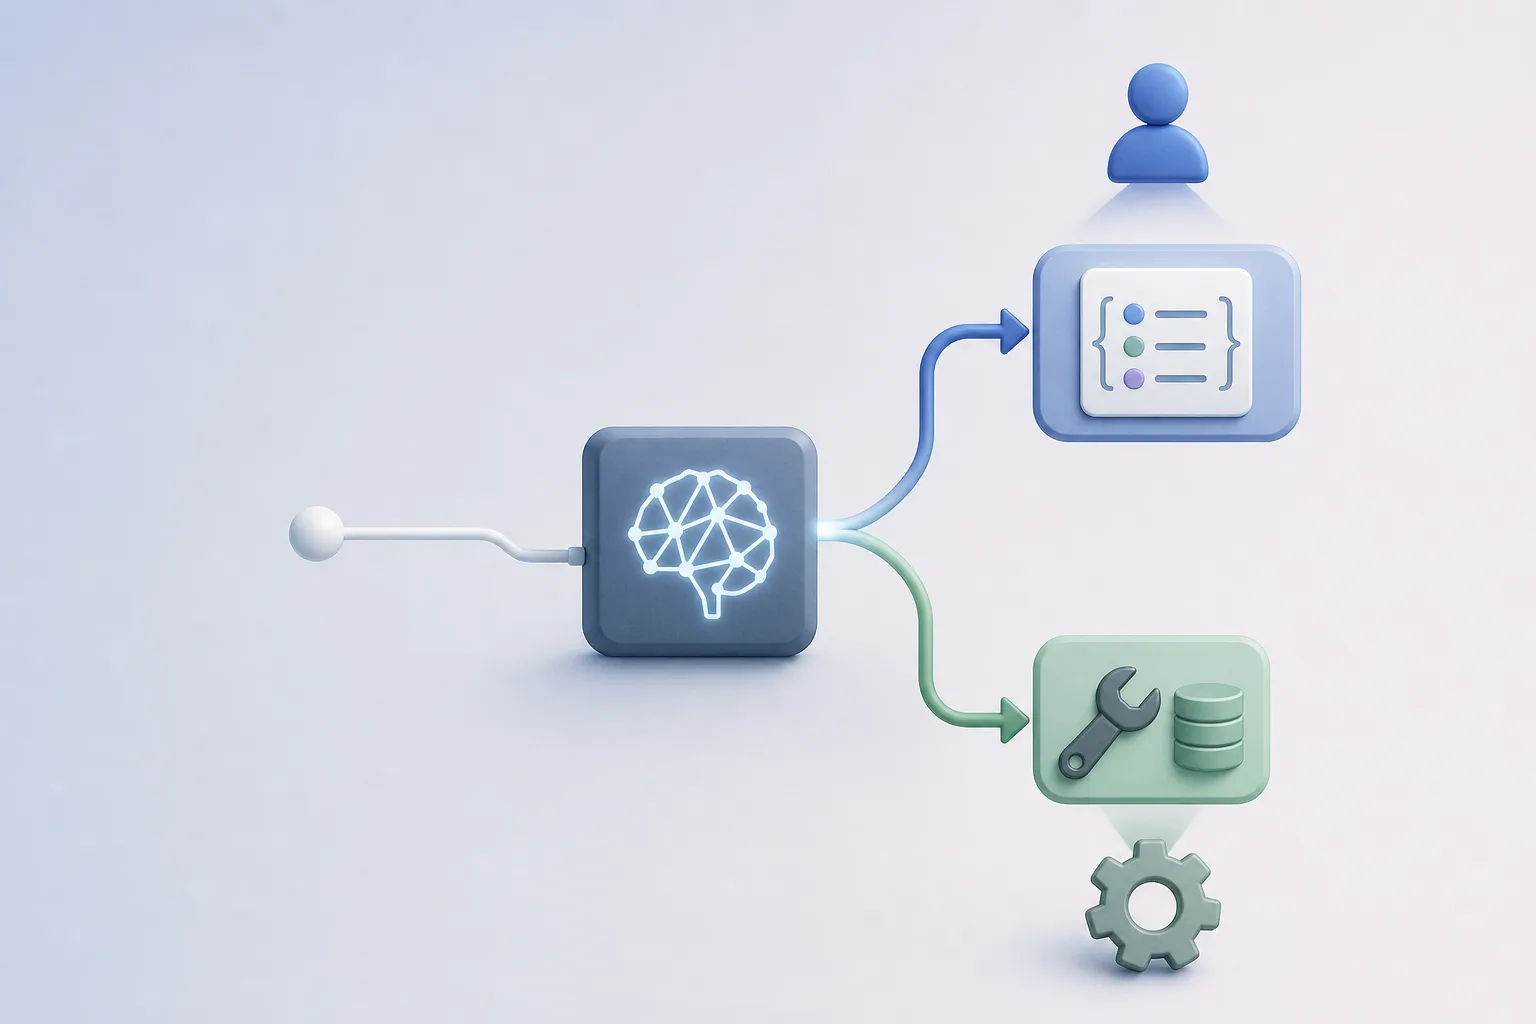
OpenAI’s documentation draws a useful line between function calling and structured output. The model can either produce a structured response for the user or propose an application action that your code executes. That distinction sounds subtle until you build the UI around it. If the model is allowed to “do” the action implicitly, then the front end can no longer tell whether the result came from a verified execution path or from a malformed assistant message that only looked authoritative.
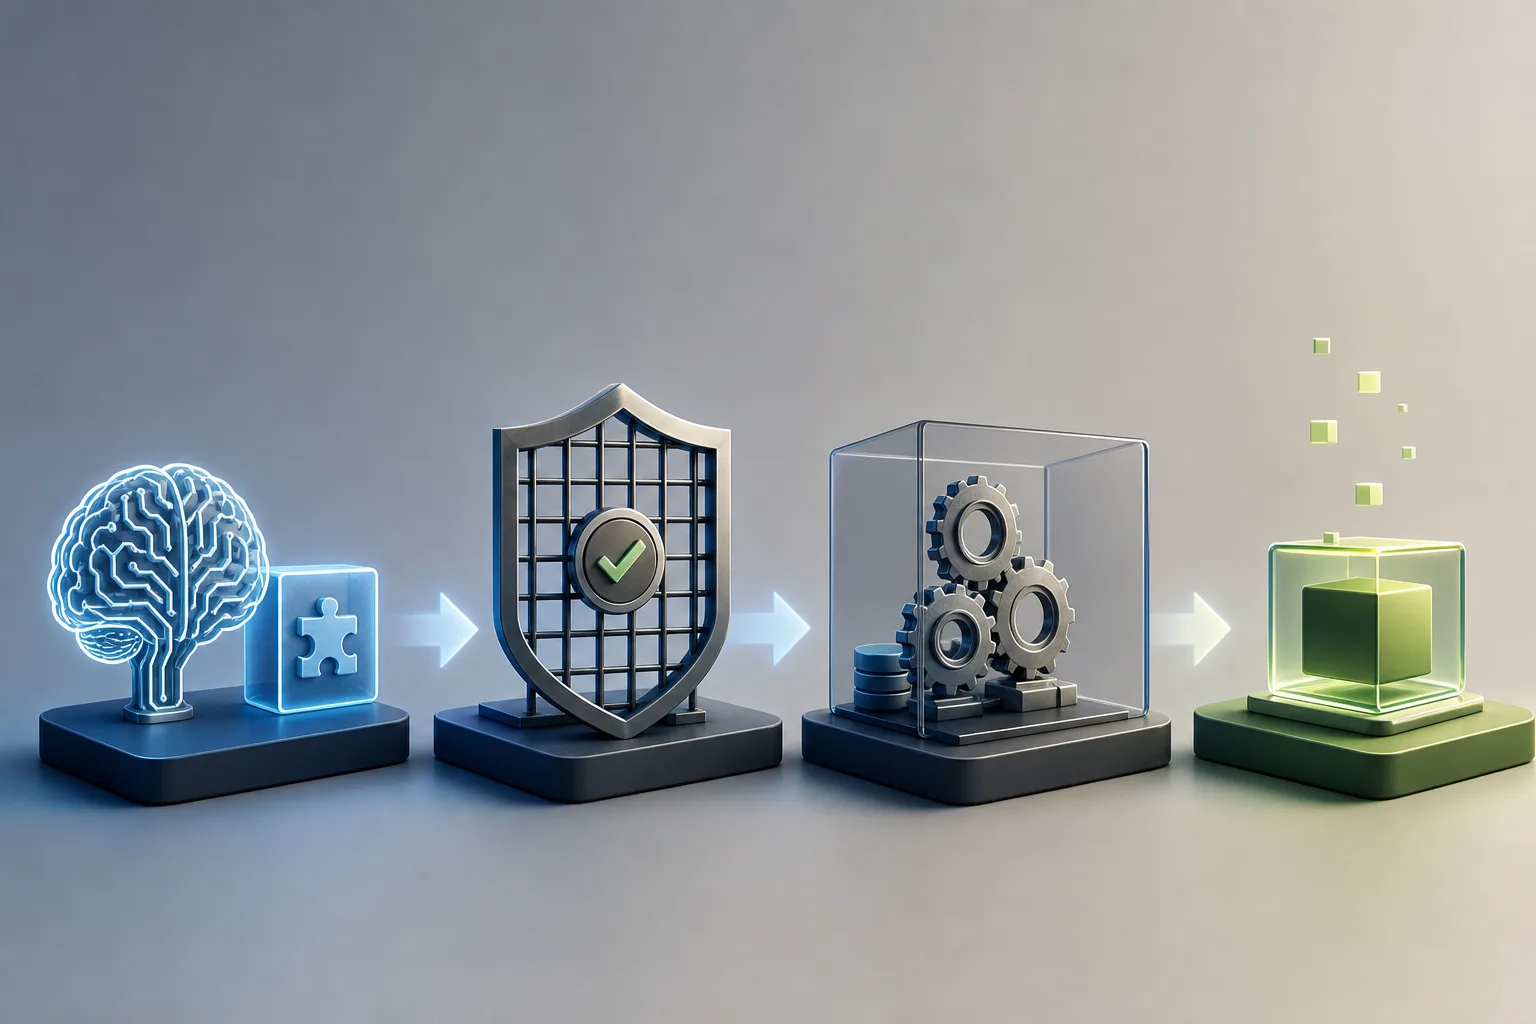
The article’s fixture uses that distinction deliberately. A proposed tool call enters the application as a JSON string. The application parses the outer wrapper, validates the function name, parses the argument JSON, and rejects anything that is missing required keys or contains keys the schema does not permit. Only after that validation does the application look up a tool implementation and call a commit function with the resulting value. That sequence makes the boundary visible: proposal, validation, execution, commit.
The important part is what the fixture leaves out. It does not pretend to be a production OpenAI integration, a networked database transaction, or a full chat UI. It is intentionally small enough to show ownership of each step. The model proposes; the app decides whether to accept; the tool executes; the commit updates the interface. That is the contract the rest of the article keeps testing and refining. This is the same design direction the OpenAI docs recommend when function calling is used to connect the model to tools or data, while structured outputs are better when the model should answer in a fixed schema rather than trigger an action.
- Proposal is not permission.
- Validation happens before execution.
- The UI commits only after a verified result.
export function parseToolCall(raw) {
  if (typeof raw !== 'string') {
    throw new TypeError('tool call must be a JSON string');
  }

  let parsed;
  try {
    parsed = JSON.parse(raw);
  } catch {
    throw new SyntaxError('tool call is not valid JSON');
  }

  if (!parsed || typeof parsed !== 'object' || Array.isArray(parsed)) {
    throw new TypeError('tool call must be a JSON object');
  }

  return parsed;
}

export function validateFunctionCall(call, schema) {
  if (!call || typeof call !== 'object' || Array.isArray(call)) {
    throw new TypeError('call must be an object');
  }
  if (!schema || typeof schema !== 'object' || Array.isArray(schema)) {
    throw new TypeError('schema must be an object');
  }

  const { name, arguments: args } = call;
  const { name: expectedName, required = [], allowedKeys = [] } = schema;

  if (typeof name !== 'string' || name.length === 0) {
    return { ok: false, reason: 'missing function name' };
  }
  if (name !== expectedName) {
    return { ok: false, reason: `unexpected function name: ${name}` };
  }
  if (typeof args !== 'string') {
    return { ok: false, reason: 'missing arguments string' };
  }

  let parsedArgs;
  try {
    parsedArgs = JSON.parse(args);
  } catch {
    return { ok: false, reason: 'arguments are not valid JSON' };
  }
  if (!parsedArgs || typeof parsedArgs !== 'object' || Array.isArray(parsedArgs)) {
    return { ok: false, reason: 'arguments must decode to an object' };
  }

  for (const key of required) {
    if (!(key in parsedArgs)) {
      return { ok: false, reason: `missing required argument: ${key}` };
    }
  }
  for (const key of Object.keys(parsedArgs)) {
    if (!allowedKeys.includes(key)) {
      return { ok: false, reason: `unexpected argument: ${key}` };
    }
  }

  return { ok: true, arguments: parsedArgs };
}

export function runToolBoundaryWorkflow({ rawToolCall, schema, tools, commit }) {
  if (!tools || typeof tools !== 'object') {
    throw new TypeError('tools map must be provided');
  }
  if (typeof commit !== 'function') {
    throw new TypeError('commit must be a function');
  }

  const call = parseToolCall(rawToolCall);
  const validation = validateFunctionCall(call, schema);
  if (!validation.ok) {
    return { status: 'rejected', reason: validation.reason };
  }

  const tool = tools[schema.name];
  if (typeof tool !== 'function') {
    return { status: 'rejected', reason: `no tool registered for ${schema.name}` };
  }

  const result = tool(validation.arguments);
  if (result && typeof result === 'object' && result.cancelled) {
    return { status: 'cancelled', reason: result.reason || 'tool cancelled' };
  }

  const committed = commit({ name: schema.name, input: validation.arguments, output: result });
  return { status: 'committed', result: committed };
}

export function createFixtureTool(name, behavior) {
  if (typeof behavior !== 'function') {
    throw new TypeError('behavior must be a function');
  }
  return (args) => behavior(args, name);
}
SourcesOpenAI: Structured Outputs (opens a new tab)OpenAI: Function calling (opens a new tab)
A tiny fixture makes the full flow reproducible
The most useful part of the fixture is not the helper names; it is the fact that each step has a single owner. `parseToolCall` owns the outer JSON parse and type check. `validateFunctionCall` owns the schema-shaped checks. `runToolBoundaryWorkflow` owns orchestration: it decides whether the call is rejected, cancelled, or committed. The tool itself owns the application behavior, and the commit callback owns the user-visible state change. Because those responsibilities are split, the test can fail for the correct reason instead of collapsing everything into one opaque “did the model work?” assertion.
That separation is especially important for function-calling articles because the API contract and the application contract are not the same thing. OpenAI’s documentation says function calling connects a model to external systems and data. It does not say the model itself becomes the authority for those systems. The fixture encodes that boundary by taking a raw tool call as data, not as an execution instruction. If the schema or tool map does not agree with the proposal, the workflow returns a rejection object and never reaches commit. If the tool reports cancellation, the workflow stops before commit as well.
This is a better teaching shape than a generic “call the API and print the response” example because it makes the hidden control flow visible. The app can reject an invalid proposal before any side effect. The app can stop a blocked action even after the schema looked correct. The app can still commit a successful action with the exact arguments that were validated. Those three paths are the real contract a user interface must respect when it fronts a tool-capable model.
- Outer JSON parsing is separate from argument parsing.
- A missing tool ends in a rejection, not a crash.
- Cancellation is a distinct outcome from success.
Cancellation is a tool result, not a UI guess
One easy mistake is to treat cancellation as if it were just another kind of transport failure. In the fixture, cancellation is a deliberate return shape from the tool implementation: `{ cancelled: true, reason: '...' }`. That design keeps the application boundary explicit. The tool may decide that the requested action is blocked by policy or cannot continue with the current state. When that happens, the workflow returns `status: 'cancelled'` and never calls `commit`. The UI can then keep its previous state instead of replacing it with a false success.
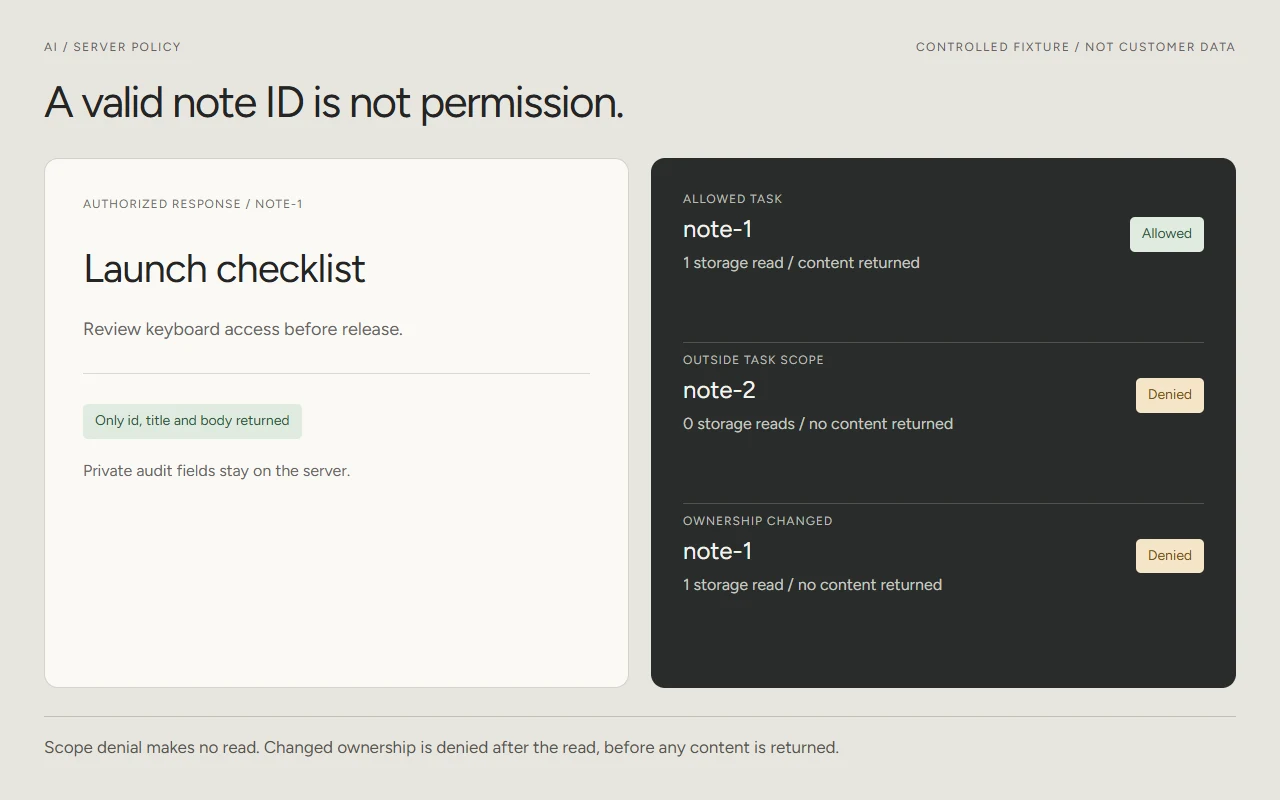
That distinction matters because the UI does not own every decision. A user interface might know that a request was sent, but only the application layer knows whether the call was acceptable for the current account, whether a resource was available, or whether a downstream dependency chose to stop. If the model proposes a weather lookup for a restricted location, the app should not manufacture a successful result simply because the proposal shape was valid. Validation is necessary, but it is not sufficient. The tool’s outcome still needs to be interpreted before any state changes are committed.
The simple workflow here leaves one limit in place on purpose: it only interprets the tool result after execution begins. It does not solve authorization by itself, and it does not prevent a poorly designed tool from doing too much work before returning cancellation. That means the article’s boundary is useful only if you keep sensitive decisions in the app and not in the prompt. The model may help choose a tool; it should not be trusted to decide whether the action is allowed.
- Cancellation is a returned outcome, not a thrown UI exception.
- A valid schema does not override app policy.
- The UI should preserve the previous state when the action is blocked.
Commit after verification, not before
The commit callback is the most important line of defense in the fixture because it represents the only place where the user-facing state changes. That ordering is deliberate. The workflow does not call `commit` when the raw tool call is malformed. It does not call `commit` when the schema validation fails. It does not call `commit` when the tool marks the action as cancelled. Only the successful path reaches the commit function, and the commit receives the exact validated arguments alongside the tool output.
That shape is useful because it reflects how a real application should think about UI updates. The UI should not be updated on the basis of a proposal. It should be updated on the basis of a verified execution result. If a model suggests a function call, the app can still decide that the proposal is incomplete, the arguments are invalid, or the requested action is outside policy. A commit protocol gives the application one place to centralize the final state change after those checks have passed.
The function-calling guide recommends strict schemas for tool calls when possible, and structured outputs for responses that should match a fixed schema. This article uses the stricter option because the point is not to accept arbitrary assistant text and hope it is useful. The point is to make the proposal machine-checkable before the app acts. The commit protocol completes that discipline by making the UI change dependent on the app’s own verification, not on the model’s confidence or conversational style.
- Commit is downstream of validation and tool execution.
- The app, not the model, owns the final state change.
- Strict schemas reduce the surface area of a bad proposal.
import test from 'node:test';
import assert from 'node:assert/strict';
import { createFixtureTool, runToolBoundaryWorkflow, validateFunctionCall } from './main.mjs';

test('commits only after a valid proposed function call is executed', () => {
  const schema = {
    name: 'get_weather',
    required: ['location'],
    allowedKeys: ['location'],
  };
  const tools = {
    get_weather: createFixtureTool('get_weather', ({ location }) => ({
      forecast: `sunny in ${location}`,
    })),
  };
  const commits = [];

  const outcome = runToolBoundaryWorkflow({
    rawToolCall: JSON.stringify({ name: 'get_weather', arguments: JSON.stringify({ location: 'Bogotá' }) }),
    schema,
    tools,
    commit(entry) {
      commits.push(entry);
      return { uiState: 'updated', entry };
    },
  });

  assert.equal(outcome.status, 'committed');
  assert.equal(commits.length, 1);
  assert.deepEqual(commits[0], {
    name: 'get_weather',
    input: { location: 'Bogotá' },
    output: { forecast: 'sunny in Bogotá' },
  });
});

test('rejects a proposed call that is missing required arguments', () => {
  const schema = {
    name: 'get_weather',
    required: ['location'],
    allowedKeys: ['location'],
  };

  const validation = validateFunctionCall(
    { name: 'get_weather', arguments: JSON.stringify({}) },
    schema,
  );

  assert.equal(validation.ok, false);
  assert.match(validation.reason, /missing required argument: location/);
});

test('stops before commit when the tool cancels the action', () => {
  const schema = {
    name: 'get_weather',
    required: ['location'],
    allowedKeys: ['location'],
  };
  let committed = false;
  const tools = {
    get_weather: createFixtureTool('get_weather', ({ location }) => {
      if (location === 'restricted') {
        return { cancelled: true, reason: 'location blocked by app policy' };
      }
      return { forecast: 'ok' };
    }),
  };

  const outcome = runToolBoundaryWorkflow({
    rawToolCall: JSON.stringify({ name: 'get_weather', arguments: JSON.stringify({ location: 'restricted' }) }),
    schema,
    tools,
    commit() {
      committed = true;
      return { uiState: 'updated' };
    },
  });

  assert.equal(outcome.status, 'cancelled');
  assert.equal(committed, false);
  assert.match(outcome.reason, /blocked by app policy/);
});
SourcesOpenAI: Structured Outputs (opens a new tab)OpenAI: Function calling (opens a new tab)
Test the order that can fail, not only the happy path
The tests matter because the boundary is easy to describe and easy to get wrong. A test that only proves the valid case would miss the two mistakes that cause the most confusion: accepting a malformed call and committing a cancelled action. The fixture’s Node test file covers both, plus the success path. That means the regression suite checks the one thing the article cares about: the application should never commit before the proposal is validated and the tool result is known.
The valid-path test constructs a schema for `get_weather`, passes a raw tool call containing a JSON-stringified argument object, and asserts that the commit callback received the validated input and the tool’s output. The missing-argument test calls `validateFunctionCall` directly and expects a rejection reason that names the absent key. The cancellation test returns `{ cancelled: true }` from the tool and asserts that commit was never called. Together, those tests establish the ordering rule better than a snapshot or an integration log would, because they isolate the exact failure and exact boundary.
There is still a useful negative limit here. The fixture does not claim to test OpenAI’s hosted API behavior, model selection, or the SDK’s transport layer. It also does not simulate the full Responses output shape with reasoning items or multiple tool calls. That is a feature, not a flaw, for this article. The goal is to prove the app-side boundary with deterministic inputs, not to pretend a local test can certify the provider’s runtime contract. The docs support the boundary decision; the fixture supports the application behavior.
- Happy path, malformed input, and cancellation are all separate tests.
- The suite proves ordering, not provider uptime.
- A local fixture can verify the app contract without a live API call.
SourcesOpenAI: Structured Outputs (opens a new tab)OpenAI: Function calling (opens a new tab)
Use the model for proposals and your app for authority
The simplest decision rule is the one the fixture makes visible. If the model should answer in a fixed schema, Structured Outputs is the better fit. If the model should propose an action that your app will execute, function calling is the better fit. In both cases, the application still owns validation, authorization, and the final commit to the user-facing state. That ownership does not disappear just because the model produced well-formed JSON.
The article’s pattern is intentionally conservative. It accepts only the expected function name, only the expected argument keys, and only the execution path that ends with a verified commit. That strictness is the point. It keeps malformed proposals from reaching side effects, it keeps blocked actions from looking successful, and it gives the UI a clear place to stop. The pattern is small enough to test locally and narrow enough to understand without a live API call.
The limits are just as important. This fixture does not remove the need for server-side permission checks, durable audit logs, or provider-specific handling when you use the real Responses API. It does not guarantee that a model will choose the right tool. It does not protect you if the tool itself is too powerful. What it does do is make the boundary visible enough to verify, which is the first step in making a tool-capable model safe enough to wire into a product.
- Use function calling for actions and Structured Outputs for fixed-schema answers.
- Keep authorization in the application, not in the prompt.
- Treat the local fixture as a boundary test, not as a provider certification.
SourcesOpenAI: Structured Outputs (opens a new tab)OpenAI: Function calling (opens a new tab)