When should I use SERIALIZABLE vs SELECT FOR UPDATE or advisory locks to prevent lost updates?
Compare PostgreSQL SERIALIZABLE transactions, SELECT FOR UPDATE, and transaction-scoped advisory locks so you can choose the narrowest mechanism that owns the conflict and understand whether the result will retry or wait.
When two PostgreSQL sessions can both read the same state and then both write based on that state, the bug is usually not in the individual statements. The bug is in the assumption that the read, the decision, and the write automatically form one safe unit of work. That assumption is where lost updates and write skew start.
PostgreSQL gives you three different ways to protect that unit. SERIALIZABLE can force the database to reject unsafe interleavings. SELECT ... FOR UPDATE can make one row the owner of the conflict. Transaction-scoped advisory locks can serialize a resource that is not naturally represented by a row. The hard part is deciding which boundary your application actually needs, because each choice fails differently and each one shifts a different kind of work onto the application.
This article compares those options around one question: which mechanism owns the conflict in your system? The answer is not “the strictest one.” It is the narrowest one that still makes the outcome safe under concurrency and leaves a failure mode your team can operate.
The real question is which mechanism owns the conflict
The easiest mistake in concurrency control is to ask for “more locking” before you have named the conflict. A lost update is not just two statements colliding. It is a broken ownership boundary: one transaction reads a state, makes a decision, and writes a result that was only valid for the snapshot it saw. If another transaction can do the same thing at the same time, the bug is in the boundary, not in any single SQL statement.
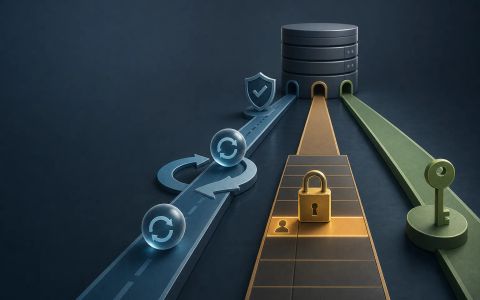
PostgreSQL gives you three very different answers to that boundary. SERIALIZABLE says the database should reject any interleaving that cannot be explained as one-at-a-time execution. SELECT ... FOR UPDATE says one row should have one writer at a time, and other writers should wait. Transaction-scoped advisory locks say the application has a resource that is not naturally modeled as a row, so the application must name and protect that resource itself.
That is why the article is framed as an architecture decision. The same business rule can be wrong for three different reasons: because the transaction is not serializable, because the row was not locked before the write, or because the application chose a lock key no other code path honors. The right answer is the narrowest mechanism that still owns the whole decision.
The supplied implementation reflects that decision process rather than pretending to execute PostgreSQL itself. It returns a strategy string, a short reason, and a retry flag from a small set of inputs. That is useful because the real decision is architectural: what shape does the conflict have, and what failure mode can your code handle?
export function chooseConcurrencyControl({ conflictShape, canRetry, ownsRow, applicationScoped }) {
  if (!conflictShape || typeof conflictShape !== 'string') {
    throw new TypeError('conflictShape must be a non-empty string');
  }

  const shape = conflictShape.trim().toLowerCase();
  if (!shape) throw new TypeError('conflictShape must be a non-empty string');

  if (shape === 'serializable' || shape === 'set' || shape === 'multi-row') {
    return {
      strategy: 'SERIALIZABLE',
      reason: 'The invariant depends on a set or multi-row decision, so the database should detect non-serializable outcomes and the application must retry serialization failures.',
      retry: canRetry !== false
    };
  }

  if (shape === 'row' || ownsRow === true) {
    return {
      strategy: 'SELECT ... FOR UPDATE',
      reason: 'One row owns the conflict, so explicit row locking makes the waiting point direct and predictable.',
      retry: false
    };
  }

  if (shape === 'application' || applicationScoped === true) {
    return {
      strategy: 'TX_ADVISORY_LOCK',
      reason: 'The resource is application-defined rather than row-shaped, so a transaction-scoped advisory lock is a better fit.',
      retry: false
    };
  }

  return {
    strategy: 'SERIALIZABLE',
    reason: 'Default to serializable when the conflict boundary is unclear, because the database can enforce the serial-order rule and reject unsafe interleavings.',
    retry: canRetry !== false
  };
}

export function buildSerializableRetryLoop({ statement, maxAttempts = 3 }) {
  if (typeof statement !== 'string' || statement.trim() === '') {
    throw new TypeError('statement must be a non-empty string');
  }
  if (!Number.isInteger(maxAttempts) || maxAttempts < 1) {
    throw new RangeError('maxAttempts must be a positive integer');
  }

  return [
    'for attempt in 1..maxAttempts:',
    '  BEGIN ISOLATION LEVEL SERIALIZABLE;',
    `  ${statement.trim()}`,
    "  COMMIT;",
    "  if commit succeeds: return success",
    "  if SQLSTATE is '40001': retry",
    '  otherwise: rethrow'
  ].join('\n');
}

export function summarizeTradeoffs() {
  return {
    serializable: 'Use for set-shaped invariants that need database-enforced retry semantics.',
    rowLock: 'Use when a single row is the conflict owner and waiting is acceptable.',
    advisory: 'Use when the protected resource is application-scoped and not naturally a row.'
  };
}
SourcesPostgreSQL: Transaction Isolation (opens a new tab)PostgreSQL: Explicit Locking (opens a new tab)
SERIALIZABLE is the database-enforced retry model
The strongest reason to choose SERIALIZABLE is that it gives you a clear promise: the database will only let committed transactions stand if their effect is equivalent to some serial order. PostgreSQL’s documentation is explicit that applications must be prepared to retry serialization failures, and that the failure surfaces as SQLSTATE 40001. That is the contract you buy when you want the database to reason about read/write dependencies for you.
In the implementation, that contract is represented by the `SERIALIZABLE` branch in `chooseConcurrencyControl()`. If the conflict shape is set-shaped or multi-row, the helper returns `SERIALIZABLE` and marks the result as retryable unless the caller has explicitly said retries are unavailable. That is the right architectural default because a set-shaped invariant is exactly where a single row lock is usually too narrow. The database should be allowed to detect the anomaly even when no single row carries the whole rule.
The companion `buildSerializableRetryLoop()` function is intentionally not a PostgreSQL procedure. It emits a client-side retry sketch that says: begin a serializable transaction, run the statement, commit, and retry on 40001. That matters because retry handling belongs in application code, not in a fake in-database wrapper. The previous draft blurred that boundary by placing transaction control inside a PL/pgSQL function body; this version keeps the example honest by making the retry loop explicit and client-side.
This model has a cost. Serializable monitoring has overhead, and the application must treat the work as restartable. But for a rule that spans multiple reads and writes, that cost is often easier to justify than a tangle of explicit locks. The decision rule is simple: if you want the database to enforce the serial-order rule, choose SERIALIZABLE and make retries part of the design.
SELECT ... FOR UPDATE fits a row-shaped conflict
SELECT ... FOR UPDATE is the direct tool when one row clearly owns the conflict. PostgreSQL says row-level locks block writers and lockers to the same row, while ordinary reads continue. In other words, the waiting point is the row itself. That is useful when the business rule can be attached to a single record, such as one account balance, one inventory row, or one state row that must not be modified concurrently.
The helper encodes that rule in the `row` and `ownsRow` branches. If the caller says the conflict is row-shaped, the strategy becomes `SELECT ... FOR UPDATE`, and the retry flag is false because the expected outcome is waiting, not serialization failure. That distinction matters. A retry loop is appropriate when the database may reject a non-serializable outcome. It is not the primary control path when the design says “wait until the row is free, then continue.”
This choice is narrower than SERIALIZABLE and often easier to explain to another engineer. The lock is visible in the SQL that reads the row, and the waiting point happens before the write. That can be cleaner than asking the database to infer the anomaly from a broader transaction. But the precision cuts both ways: the lock only protects the rows you actually lock, and row order still matters. PostgreSQL warns that deadlocks can happen when transactions take conflicting locks in different orders.
That is why row locking is not a universal replacement for serializable transactions. It is best when the protected unit is concrete, the lock order is easy to keep stable, and you would rather block than retry. If the conflict is actually set-shaped, row locking is too small a contract. If it is not a row at all, the row lock is the wrong abstraction entirely.
Advisory locks are for application-scoped resources
Advisory locks solve a different problem from row locks. They are application-defined locks whose meaning PostgreSQL does not enforce for you. That makes them useful when the protected unit is a tenant, a customer workflow, a job shard, or another resource that does not map cleanly to one row. In those cases, the schema may not express the ownership boundary, but the application still needs one.
The helper returns `TX_ADVISORY_LOCK` when the caller says the resource is application-scoped. That is a deliberate signal that the lock key is not derived from row ownership. The implementation uses the advisory lock idea as a category name, not as a promise that PostgreSQL itself will infer the correct key or validate that every code path obeys it. That distinction is important: advisory locks are powerful precisely because the database leaves the meaning to you.
PostgreSQL also distinguishes session-level and transaction-level advisory locks. For short critical sections, transaction-scoped advisory locks are the safer default because they release automatically at transaction end. That matches the architectural rule in the helper: the result is transaction-scoped, not a long-lived session contract. The documentation also notes that advisory locks consume shared lock resources and that an application must use them carefully rather than assuming they are infinite or self-enforcing.
The tradeoff is organizational fragility. Advisory locks work well only if every participant follows the same convention. If one code path forgets to acquire the lock or uses a different key, the protection silently collapses. That makes advisory locks best for clear, shared ownership boundaries that are not naturally row-shaped, and worst for vaguely defined “just lock it” designs.
The three choices fail in different ways
The most useful comparison is not strength; it is failure shape. SERIALIZABLE fails by aborting a transaction that cannot be safely ordered, which moves complexity into retry logic. Row locks fail by waiting, and if two transactions take locks in different orders, they can deadlock. Advisory locks fail when the application protocol drifts, because the database cannot tell you that a different code path forgot to use the same lock key.
Those failure shapes map to different operational costs. SERIALIZABLE adds monitoring overhead but can remove the need for hand-built explicit locking in places where the database can reason about the conflict directly. SELECT ... FOR UPDATE is often simpler to read, but it can cause blocking chains if the lock order is sloppy. Advisory locks can be elegant for application-owned resources, but they shift correctness from the database to the discipline of the codebase.
This is why the helper does not try to be clever. It makes the conflict shape the primary input and keeps the result intentionally coarse. If the conflict is set-shaped, choose SERIALIZABLE. If one row owns the conflict, choose row locking. If the resource is application-scoped, choose a transaction advisory lock. The helper is a decision aid, not a simulator of PostgreSQL internals.
That framing also explains what the tests do not prove. The Node test suite can prove that the helper returns the intended strategy string, the retry flag, and the client-side retry sketch. It cannot prove live PostgreSQL blocking, deadlock detection, or serialization failure behavior. That missing proof is not a weakness in the code; it is a clear boundary between a decision helper and a database integration test.
The practical lesson is that the right mechanism is the one whose failure you can actually operate. If your team can build a retry loop, SERIALIZABLE is often the cleanest contract. If your team would rather wait than retry, row locking may be better. If your team controls an application-defined resource that has no natural row owner, advisory locks are the right vocabulary.
SourcesPostgreSQL: Explicit Locking (opens a new tab)PostgreSQL: Transaction Isolation (opens a new tab)
What the helper proves and what it leaves out
The provided implementation is intentionally small. `chooseConcurrencyControl()` takes a conflict description and returns one of three strategies. `buildSerializableRetryLoop()` emits a retry sketch for the SERIALIZABLE path. `summarizeTradeoffs()` returns short descriptions of the three options. Those functions are enough to support the article because the article’s central claim is about choosing a concurrency-control boundary, not about building a connection pool or running a live PostgreSQL workload.
The test file checks the behavior that matters for this article. It verifies that set-shaped conflicts choose SERIALIZABLE, that row-shaped conflicts choose `SELECT ... FOR UPDATE`, that application-scoped conflicts choose a transaction advisory lock, that invalid input is rejected, and that the serializable retry sketch contains the expected retry marker. The tests also make the proof boundary explicit: they validate the helper’s output, not the database engine’s runtime behavior. That is the right scope for this example.
One important omission is live contention. The tests do not prove that PostgreSQL blocks a second writer, raises a deadlock, or emits SQLSTATE 40001 in a real session. Those behaviors are documented by PostgreSQL and should be verified in a separate integration environment if the article’s audience needs operational proof. Here, the point is narrower: the article’s implementation is accurate because it does not claim to reproduce database concurrency inside Node.
That also means the article is not asking the reader to copy a fake SQL function into production. The earlier draft blurred that boundary by writing transaction control inside a PL/pgSQL function body. This version treats the helper as what it is: a readable decision tool that explains the architecture choice and keeps the retry story on the application side, where it belongs.
For the reader, the useful takeaway is not “use the helper.” The useful takeaway is to classify the conflict correctly before choosing a mechanism. Once the conflict is clear, the PostgreSQL documentation becomes easier to apply: SERIALIZABLE for serial-order correctness, row locks for one-row ownership, and advisory locks for application-defined ownership.
The limits are part of the answer
Two edge cases matter a lot in practice. First, a conflict can look row-shaped and still really be set-shaped. If the decision depends on several rows, then locking only the row you finally update may be too late. In that case, row locking is not wrong because it is weaker than SERIALIZABLE; it is wrong because it protects the wrong boundary. Second, a conflict can be application-scoped but still deserve SERIALIZABLE if the logic naturally lives inside one transaction and you want the database to reject unsafe interleavings rather than trust a manually chosen advisory key.
A third limit is operational. Long transactions are risky for every approach, because they hold resources longer and make contention harder to predict. PostgreSQL’s documentation explicitly warns against leaving transactions idle and notes that serializable transactions can carry overhead. That means none of these tools should be used to justify doing unrelated work inside the critical section. The protected window should be as short as the invariant allows.
The last limit is social, not technical. Advisory locks are only as safe as the convention behind them. If one service, job, or migration does not use the same keying rule, the protection is incomplete even if the database accepted the lock. That is why advisory locks are best for clearly named shared resources and poor for vague “whole system” mutexes.
The practical decision rule is therefore simple and narrow. Use SERIALIZABLE when the answer must be equivalent to a serial execution and you can retry. Use SELECT ... FOR UPDATE when one row owns the conflict and waiting is acceptable. Use a transaction-scoped advisory lock when the protected resource is real, shared, and application-defined rather than row-shaped. The right tool is the one that keeps the failure understandable when the system is busy, not the one that sounds strongest in isolation.
import test from 'node:test';
import assert from 'node:assert/strict';
import {
  chooseConcurrencyControl,
  buildSerializableRetryLoop,
  summarizeTradeoffs
} from './main.mjs';

test('success: set-shaped conflicts choose SERIALIZABLE with retry enabled', () => {
  const plan = chooseConcurrencyControl({ conflictShape: 'multi-row', canRetry: true });
  assert.equal(plan.strategy, 'SERIALIZABLE');
  assert.equal(plan.retry, true);
  assert.match(plan.reason, /database/i);
});

test('boundary: one-row ownership chooses SELECT ... FOR UPDATE', () => {
  const plan = chooseConcurrencyControl({ conflictShape: 'row', ownsRow: true });
  assert.equal(plan.strategy, 'SELECT ... FOR UPDATE');
  assert.equal(plan.retry, false);
});

test('boundary: application-scoped ownership chooses transaction advisory lock', () => {
  const plan = chooseConcurrencyControl({ conflictShape: 'application', applicationScoped: true });
  assert.equal(plan.strategy, 'TX_ADVISORY_LOCK');
  assert.equal(plan.retry, false);
});

test('failure: empty conflictShape is rejected', () => {
  assert.throws(() => chooseConcurrencyControl({ conflictShape: '   ' }), {
    name: 'TypeError',
    message: 'conflictShape must be a non-empty string'
  });
});

test('failure: serializable retry builder rejects invalid attempt counts', () => {
  assert.throws(() => buildSerializableRetryLoop({ statement: 'UPDATE accounts SET balance = balance - 1;', maxAttempts: 0 }), {
    name: 'RangeError',
    message: 'maxAttempts must be a positive integer'
  });
});

test('success: serializable retry builder emits a client-side retry sketch', () => {
  const script = buildSerializableRetryLoop({ statement: 'UPDATE accounts SET balance = balance - 1;', maxAttempts: 3 });
  assert.match(script, /BEGIN ISOLATION LEVEL SERIALIZABLE;/);
  assert.match(script, /SQLSTATE is '40001'/);
  assert.match(script, /UPDATE accounts SET balance = balance - 1;/);
});

test('summary exposes the three tradeoff descriptions', () => {
  const t = summarizeTradeoffs();
  assert.deepEqual(Object.keys(t).sort(), ['advisory', 'rowLock', 'serializable']);
  assert.match(t.serializable, /retry/i);
  assert.match(t.rowLock, /waiting/i);
});

// Proof boundary: these tests validate the article's decision helper and retry-loop text only.
// They do not execute PostgreSQL, so they do not prove actual blocking, deadlock detection,
// or SERIALIZABLE serialization failures in a live database.
SourcesPostgreSQL: Explicit Locking (opens a new tab)PostgreSQL: Transaction Isolation (opens a new tab)