How do I run independent I/O tasks together and handle a failing task without leaving other work running unnoticed?
Use asyncio task groups, cancellation, and bounded waits so one failed I/O worker stops its siblings and every task is awaited before control returns.
Independent I/O tasks are easy to start and surprisingly easy to leave running after the first failure. That is the part that trips people up: the code may already have raised an exception, but some of the work it launched is still alive in the event loop. The fix is not just “catch the error.” It is to make sure every task reaches a terminal state before the scope ends.
Python asyncio gives you the pieces for that boundary: `TaskGroup` for structured ownership, `gather()` for concurrent aggregation, `CancelledError` for cooperative shutdown, and `TimeoutError` for bounded waits. The useful question is how those pieces fit together so one failing task does not leave other work running unnoticed.
The problem is not concurrency; it is unowned work
The runnable example below is a JavaScript conceptual analogy, executed with Node.js. It uses Promise.all, AbortController and Promise.allSettled to illustrate cooperative cancellation and waiting for cleanup. It is not Python code and its tests do not execute or verify asyncio.gather(), TaskGroup, CancelledError or TimeoutError. The Python recommendations in this article come from the linked Python documentation, not from those JavaScript test results.
Running several independent I/O coroutines at the same time is normal. The bug appears when one of them fails and the calling code treats that exception as if the rest of the batch had somehow stopped with it. In asyncio, that assumption is only true when you make the ownership boundary explicit. A task that has been scheduled still exists until it finishes, fails, or is cancelled and awaited.
The practical failure is not abstract. A search refresh, file transfer, lease renewal, or API fan-out can keep going after the caller has already moved on. That is how stale work leaks through: the code has noticed a failure, but it has not actually brought the other tasks to a terminal state. The reader’s real problem is not merely “how do I start independent tasks?” It is “how do I guarantee that every task in this scope ends before I leave it?”
Python’s own documentation gives the relevant tools. `asyncio.create_task()` starts a coroutine. `TaskGroup` owns a set of tasks and waits for them all. `CancelledError` is the cooperative shutdown signal, and `TimeoutError` is the modern deadline exception to catch when a wait takes too long. The article’s point is that these are not interchangeable helpers; they solve different parts of the same ownership problem.
export class AbortError extends Error {
  constructor(message = 'Aborted') {
    super(message);
    this.name = 'AbortError';
  }
}

function sleep(ms, signal) {
  return new Promise((resolve, reject) => {
    const timer = setTimeout(done, ms);

    function done() {
      cleanup();
      resolve();
    }

    function onAbort() {
      cleanup();
      reject(new AbortError());
    }

    function cleanup() {
      clearTimeout(timer);
      signal?.removeEventListener('abort', onAbort);
    }

    if (signal?.aborted) {
      cleanup();
      reject(new AbortError());
      return;
    }

    if (signal) signal.addEventListener('abort', onAbort, { once: true });
  });
}

export async function worker(id, {
  steps = 5,
  stepMs = 10,
  signal,
  failAtStep = null,
  progress = {},
} = {}) {
  for (let i = 1; i <= steps; i++) {
    if (signal?.aborted) throw new AbortError();
    await sleep(stepMs, signal);
    progress[id] = (progress[id] ?? 0) + 1;
    if (failAtStep === i) {
      throw new Error(`worker:${id} failed at step ${i}`);
    }
  }
  return `done:${id}`;
}

export async function runNaive(numWorkers, opts = {}) {
  const { failingWorker = null, progress = {}, steps = 5, stepMs = 10 } = opts;
  const tasks = Array.from({ length: numWorkers }, (_, id) => worker(id, {
    steps,
    stepMs,
    progress,
    failAtStep: id === failingWorker ? 2 : null,
  }));
  return Promise.all(tasks);
}

export async function runSafe(numWorkers, opts = {}) {
  const { failingWorker = null, progress = {}, steps = 5, stepMs = 10 } = opts;
  const controller = new AbortController();
  const tasks = Array.from({ length: numWorkers }, (_, id) => worker(id, {
    signal: controller.signal,
    steps,
    stepMs,
    progress,
    failAtStep: id === failingWorker ? 2 : null,
  }));

  try {
    return await Promise.all(tasks);
  } catch (error) {
    if (!(error instanceof AbortError)) controller.abort();
    await Promise.allSettled(tasks);
    throw error;
  }
}
SourcesPython docs: asyncio task and task group semantics (opens a new tab)Python docs: asyncio CancelledError and TimeoutError (opens a new tab)
Why `gather()` is not the same as clean failure containment
`asyncio.gather()` is useful when you want to run awaitables concurrently and collect their results in input order. That convenience is exactly why people reach for it first. But the docs are explicit about the failure case: if `return_exceptions` is false, the first raised exception is immediately propagated to the caller, and the other awaitables are not cancelled. They keep running unless you stop them some other way.
That detail matters because it means the wrapper is not a safety boundary by itself. If you launch three workers and one fails quickly, the waiting task sees the failure, but the siblings may still be making progress in the event loop. If your code returns to the caller at that point, you have created the false appearance of completion while background work remains active. The user of the API sees an error, but the system still has live tasks.
The docs also warn about a subtle trap: once `gather()` has already been marked done by propagating an exception, calling `gather.cancel()` later will not cancel the already submitted awaitables. So the fix is not to let the error escape and hope you can clean up afterward. You need either a structured owner such as `TaskGroup` or explicit task references plus a deliberate cancellation-and-await phase before returning.
SourcesPython docs: asyncio gather and its cancellation caveats (opens a new tab)Python docs: asyncio Task cancellation (opens a new tab)
`TaskGroup` is the safest default for sibling failure
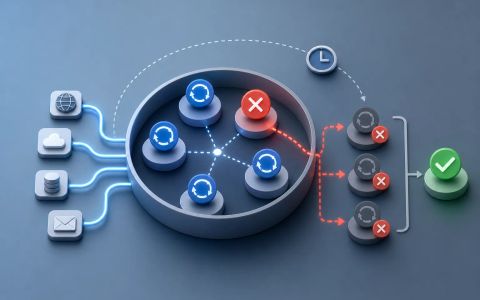
`TaskGroup` is the structured-concurrency primitive that matches this problem. Its contract is simple and stronger than `gather()`'s: all tasks created in the group are awaited when the context manager exits, and the first non-`CancelledError` failure triggers cancellation of the remaining tasks. That means failure is not just reported; it becomes the signal to close the whole scope.
This is the behavior the reader usually wants when the tasks belong to one operation. If one worker fails while the others are still in flight, the group cancels the siblings, waits for their cleanup, and then raises the resulting exception group if needed. That prevents the caller from continuing with a partly completed batch and makes the end of the operation visible in one place.
The docs also describe how the body of the `async with` block is handled. If a child task fails while the body is still active, the body task itself is cancelled so the block wakes up, but the cancellation is contained inside the context manager instead of leaking out as a stray interruption in the ordinary case. That is why `TaskGroup` is more than syntax sugar: it turns a cluster of tasks into one scope with one exit rule.
SourcesPython docs: asyncio TaskGroup (opens a new tab)Python docs: asyncio CancelledError (opens a new tab)
Timeouts and cancellation need different handling
A timeout and a cancellation request are not the same event. The asyncio docs deliberately separate them. `asyncio.timeout()` uses cancellation internally, while the deadline exception you normally handle is the built-in `TimeoutError`. That separation matters because a timeout means “stop waiting because the policy limit was reached,” not “this task failed on its own.”
`CancelledError` is also special. It is a subclass of `BaseException`, so ordinary `except Exception` handlers will not catch it. That design exists so cancellation can propagate after cleanup instead of getting swallowed by broad error handling. If a coroutine truly catches `CancelledError`, it should usually perform only cleanup and then re-raise it. The docs warn that suppressing it completely is unusual and requires clearing the cancellation state explicitly with `uncancel()`.
For this article’s problem, that means a failure boundary should not collapse everything into one generic handler. A sibling task may fail, a deadline may expire, or the caller may cancel the whole operation intentionally. The repair is to keep those outcomes distinct so you can stop the rest of the batch without turning every interruption into a misleading application error.
SourcesPython docs: asyncio Task cancellation (opens a new tab)Python docs: asyncio exceptions (opens a new tab)
What the example proves, and what it does not
The runnable fixture is a JavaScript analogy for the ownership question, not an asyncio implementation. Its worker function returns a Promise and cooperatively checks an AbortSignal between steps. runNaive starts several workers and returns Promise.all; a rejected promise does not stop the other JavaScript workers. runSafe creates an AbortController, signals cancellation after a failure, waits for all started promises with Promise.allSettled, and then throws the original error. These names belong to this fixture and are not aliases for Python APIs.
Run main.test.mjs with node --test main.test.mjs alongside main.mjs. Three independent cases check this JavaScript implementation: successful workers return results in input order, runNaive leaves sibling progress after a rejection, and runSafe has no further sibling progress after it returns an error. The failure cases use cooperative timer-driven workers. They do not establish a performance bound or a guarantee about an uncooperative dependency, a database commit, or a remote HTTP request. These are assertions to run, not a claim that a Python integration has passed.
For Python, the linked asyncio documentation is the evidence for gather, TaskGroup and cancellation semantics. The Node tests do not exercise Python exception groups, CancelledError propagation, TimeoutError conversion, shield, or TaskGroup cleanup. Before adopting the Python guidance in a service, run a native Python integration check with its actual I/O clients: verify normal completion, one child raising while a sibling is waiting, and an enclosing timeout or cancellation. Observe cleanup and outstanding tasks after the scope exits; do not infer those outcomes from the JavaScript analogy.
The analogy is useful for seeing why observing a failure and waiting for cleanup are separate actions. It does not make AbortController equivalent to TaskGroup. In Python, a coroutine that suppresses CancelledError can interfere with structured cancellation; intentionally shielded work has a different lifetime. Keep those language-specific rules separate from the local Promise behavior and use the native documentation when deciding which operation owns a task.
SourcesPython docs: asyncio Task object (opens a new tab)Python docs: asyncio shield and task creation (opens a new tab)
How to choose the right ownership boundary
If the tasks all belong to one logical operation, use `TaskGroup` first. That is the best match when one failure should stop the whole batch and the caller should not see a partially finished scope. The group expresses the ownership directly, so the code does not need to remember to cancel siblings manually after every exception. In the article’s problem, that is usually the right default.
Use `gather()` when you want concurrent results and you do not need sibling cancellation as part of the contract. It is still useful, but it solves a different problem: aggregation, not containment. If you need to preserve input order while still stopping all remaining work on failure, `gather()` alone is not enough. The boundary has to be made explicit elsewhere.
The decision rule is simple. If leaking background work would be harmful, choose the primitive that owns the tasks to completion. If a task may continue independently after the caller has moved on, then that task should not be in the same ownership group in the first place. The article’s example keeps that distinction visible so the reader can apply it to their own I/O batch without confusing concurrency with containment.
import test from 'node:test';
import assert from 'node:assert/strict';
import { runNaive, runSafe, AbortError } from './main.mjs';

const wait = (ms) => new Promise((resolve) => setTimeout(resolve, ms));

test('runSafe succeeds and returns all worker results in input order', async () => {
  const progress = {};
  const results = await runSafe(3, { steps: 3, stepMs: 1, progress });

  assert.deepEqual(results, ['done:0', 'done:1', 'done:2']);
  assert.equal(progress[0], 3);
  assert.equal(progress[1], 3);
  assert.equal(progress[2], 3);
});

test('runNaive leaves sibling work running after the first failure', async () => {
  const progress = {};

  await assert.rejects(
    runNaive(3, { steps: 20, stepMs: 2, failingWorker: 1, progress }),
    /worker:1 failed at step 2/
  );

  const before = { ...progress };
  await wait(15);
  const after = { ...progress };

  assert.ok((after[0] ?? 0) > (before[0] ?? 0) || (after[2] ?? 0) > (before[2] ?? 0));
});

test('runSafe stops sibling progress after a failure and still awaits cleanup', async () => {
  const progress = {};

  await assert.rejects(
    runSafe(3, { steps: 20, stepMs: 2, failingWorker: 1, progress }),
    /worker:1 failed at step 2/
  );

  const snapshot = { ...progress };
  await wait(15);

  assert.deepEqual(progress, snapshot);
});
SourcesPython docs: asyncio TaskGroup and gather behavior (opens a new tab)Python docs: asyncio TimeoutError and CancelledError (opens a new tab)