Why should a cancelled tool result preserve UI state instead of becoming an error?
Model tool cancellation as a preserved-state outcome instead of a UI error, so the app keeps the last good view and only commits when the tool result is actionable.
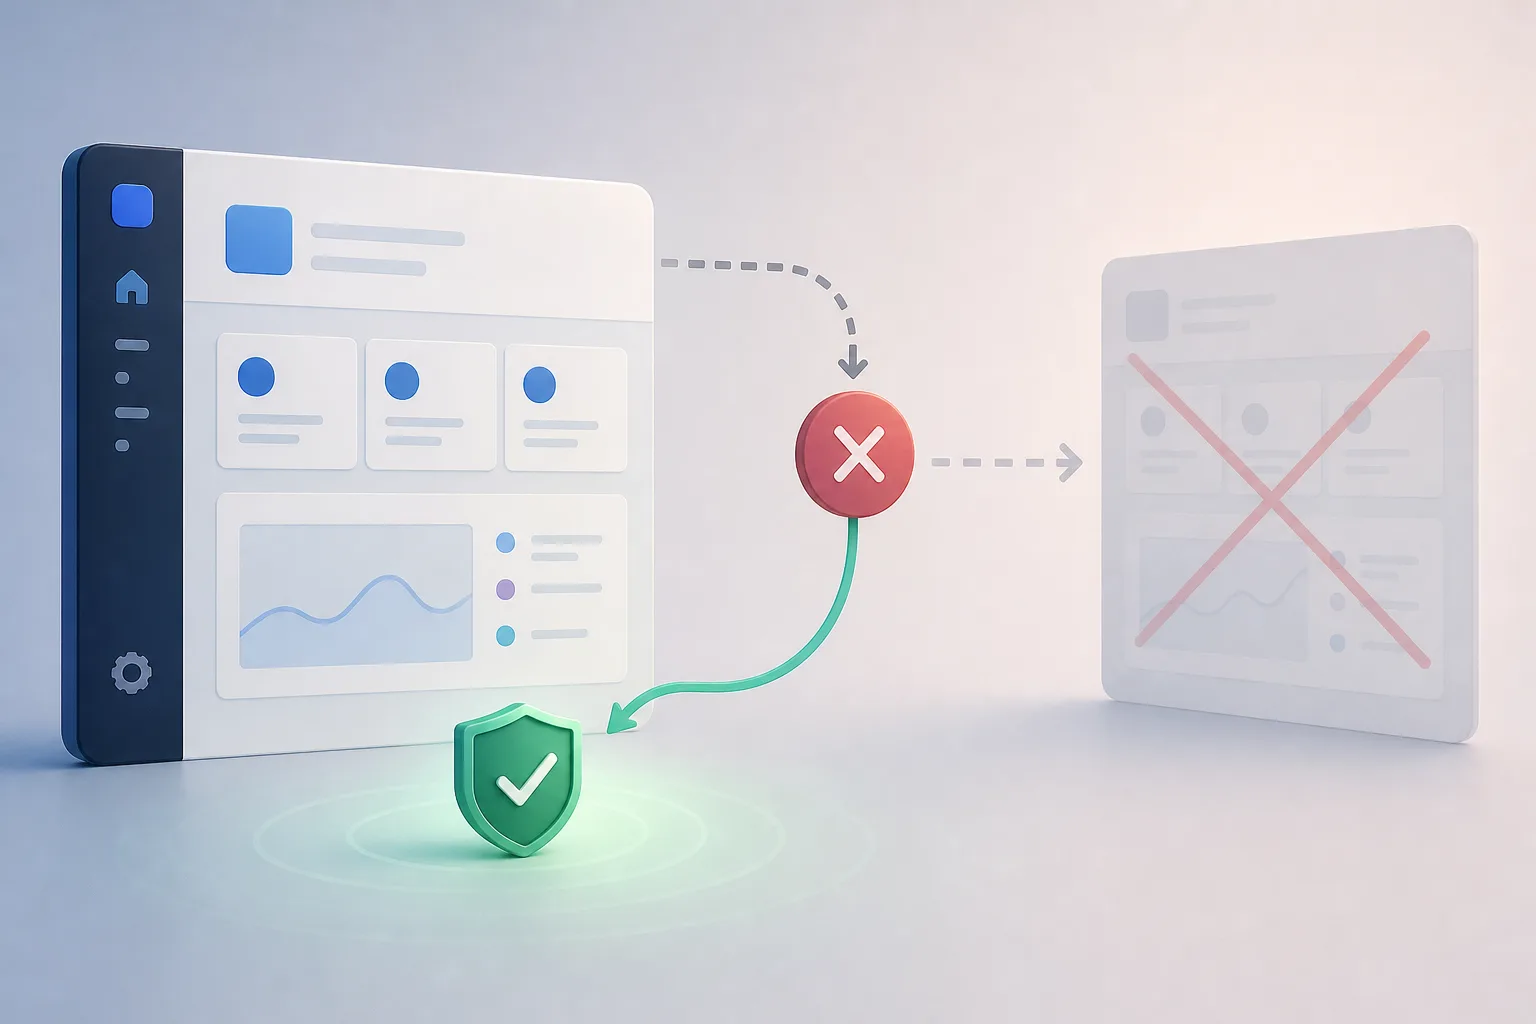
When a tool stops because the user cancelled it, the app should usually keep the last good screen instead of turning that outcome into a visible failure. That sounds obvious until the code path for cancellation and the code path for errors both feed the same UI reducer. Then a harmless stop can clear data, reset loading flags the wrong way, or show an error state that implies something broke when it did not.
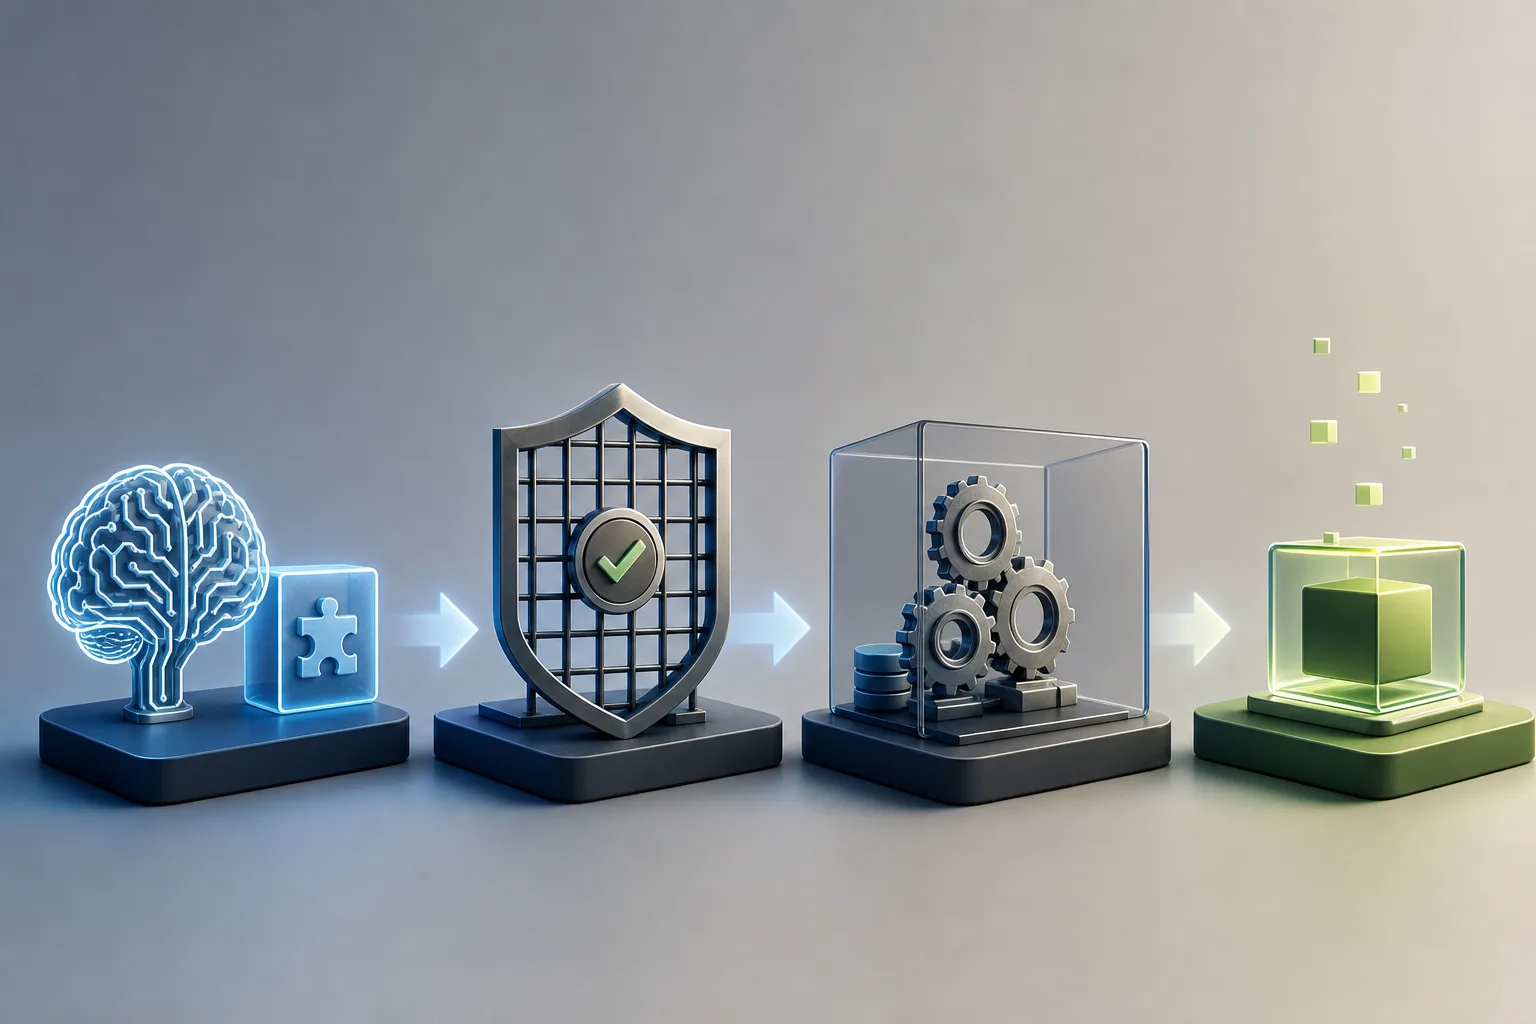
This article uses a small reducer and a matching test file to separate those outcomes. The point is not the particular merge strategy; the point is the ownership rule. A tool result can commit, preserve prior state, or surface an actionable error. Cancellation belongs in the preserve branch, because it tells the UI that the previous state is still authoritative.
Why cancellation needs its own outcome
A cancelled tool run is not the same thing as a failed tool run. In a UI, that distinction matters because the user experience should preserve the last good view when work stops for a reason that does not invalidate the current state. If the app folds cancellation into an error path, it risks clearing data, flashing a red banner, or replacing stable content with an empty failure panel even though nothing actually went wrong with the prior state.
The supplied reducer makes that choice explicit with a `status` field and a `meta.kind` result. `ok` means the tool produced a payload that can be committed. `cancelled` means the tool stopped before producing a state-changing result, so the previous state stays in place. `error` means the tool failed in a way that should be surfaced and possibly retried. The important design decision is not the syntax of the object; it is the ownership rule attached to each status.
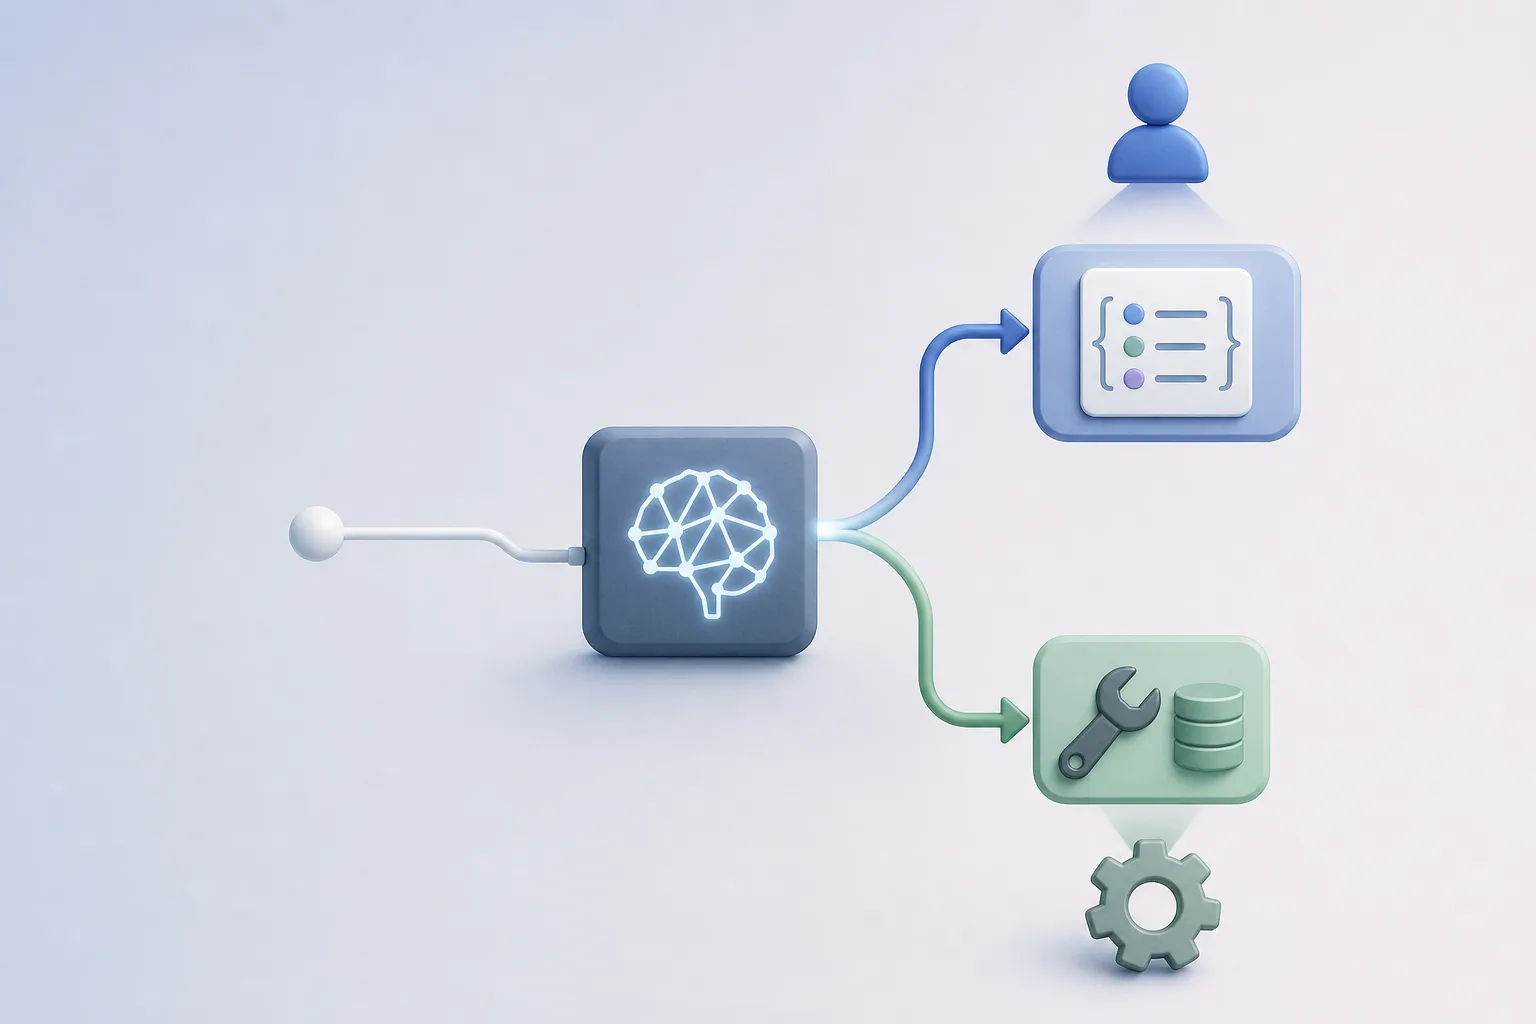
That ownership rule matches the function-calling flow described in the official docs: the application executes the tool and then decides how to turn the tool output into the next turn of state. The model can propose a function call, but the app still decides what to commit to the UI. Cancellation belongs to the app-side outcome model, not to a generic error bucket.
export function applyToolResult(prevState, toolResult) {
  // toolResult is expected to be one of:
  // { status: 'ok', payload: any }
  // { status: 'cancelled', reason?: string }
  // { status: 'error', error: any }
  // The function returns an object describing whether to commit the tool's
  // changes into the UI state and metadata to drive UI behavior.

  if (!toolResult || typeof toolResult !== 'object') {
    return {
      commit: false,
      state: prevState,
      meta: { kind: 'invalid_tool_result', message: 'Tool returned non-object' },
    };
  }

  switch (toolResult.status) {
    case 'ok':
      // Successful tool run: commit new state derived from payload.
      // For the example, we shallow-merge payload into prevState.
      return {
        commit: true,
        state: { ...prevState, ...(toolResult.payload || {}) },
        meta: { kind: 'ok' },
      };

    case 'cancelled':
      // Cancellation is not a UI-side error. We deliberately do NOT commit
      // changes and we surface a cancellation marker so the UI can preserve
      // prior state and optionally show a benign message.
      return {
        commit: false,
        state: prevState,
        meta: { kind: 'cancelled', reason: toolResult.reason ?? null },
      };

    case 'error':
      // Real tool error -- treat as actionable failure. Do not commit and
      // mark meta for UI error handling. (Different from cancellation.)
      return {
        commit: false,
        state: prevState,
        meta: { kind: 'error', error: toolResult.error ?? 'unknown' },
      };

    default:
      return {
        commit: false,
        state: prevState,
        meta: { kind: 'unknown_status', status: toolResult.status },
      };
  }
}
SourcesOpenAI Structured Outputs guide (opens a new tab)OpenAI Function calling guide (opens a new tab)
How the tool loop creates the misclassification risk
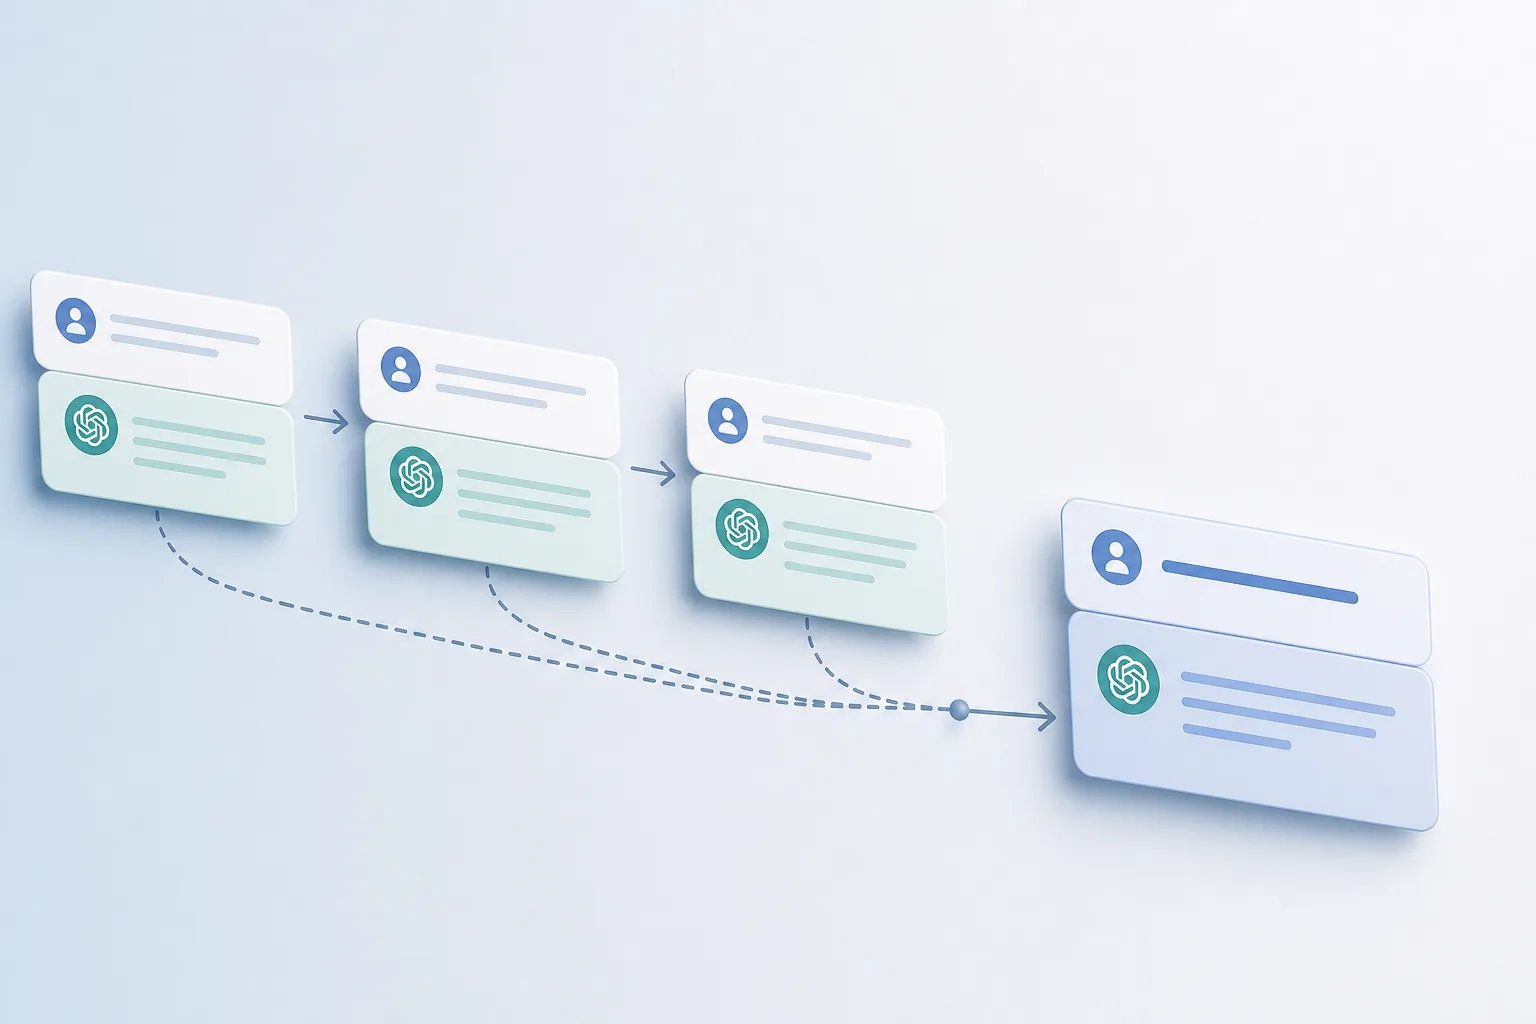
The function-calling guide describes a multi-step loop: send a request, receive a tool call, execute code on the application side, send the tool output back, and continue until the model returns a final response. That loop invites a common shortcut in UI code: treat every non-`ok` tool result as the same sort of failure. The shortcut seems harmless at first because both cancellation and error skip a commit, but they do not imply the same user-facing consequence.
If the app maps cancellation to an error state, it usually starts showing the wrong affordances. A user-aborted background lookup should not look like an unexpected server crash. A voluntary stop should not invalidate the data that was already on screen. The UI might still need a small notice, but that notice should explain that the previous state remains authoritative rather than implying the current screen is broken.
The reducer in the example preserves that boundary by returning `commit: false` for both `cancelled` and `error`, while separating them in `meta.kind`. That separation lets the UI render a non-destructive cancellation banner, keep loading spinners from becoming sticky, and avoid destroying the last known good state. The commit flag says whether to adopt the tool result; the meta object says how to explain the outcome.
What the example actually guarantees
The reducer is intentionally small. It does not try to model a full agent runtime, and it does not validate tool payloads against a JSON Schema. Instead, it demonstrates one ownership decision: the UI state should only advance when the tool result is actionable. That makes the example useful as a state-policy test, not as a complete production transport layer.
For `ok`, the code shallow-merges `toolResult.payload` into `prevState`. That is enough to show a commit path, but it also exposes a limit: a shallow merge is not safe for every domain object. Nested state, arrays, and immutable collections need a domain-specific update strategy. The example should therefore be read as a commit gate, not as a recommendation to merge every payload directly into component state.
For `cancelled`, the reducer returns the original `prevState` unchanged and sets `meta.kind` to `cancelled`. The test asserts that the visible state is preserved and that cancellation is not interpreted as an error. That is the core guarantee the article cares about. It does not guarantee network cancellation, request abortion, or browser-level task interruption; those concerns sit elsewhere in the stack and need separate tests.
Why an incomplete fix still fails
A tempting partial fix is to keep cancellation out of `error` but still commit an empty payload, perhaps by returning a new state object with no changes. That looks safe because the data values stay the same, yet it still breaks the ownership model. A no-op commit can trigger rerenders, reset derived loading flags, or wipe UI metadata that was supposed to remain attached to the previous state. In other words, preserving values is not always the same as preserving state ownership.
Another incomplete fix is to attach cancellation only to a message string and let the UI infer behavior from the presence of a notice. That is brittle because the rendering layer now has to infer whether it should keep the prior result, clear the form, or suppress a retry button. The reducer’s `commit` flag is valuable because it makes the data-flow decision explicit before the presentation layer starts guessing.
The example also shows why the `error` branch must stay distinct. If a cancelled tool run and an actual tool failure are both packed into the same generic failure path, the UI loses the ability to preserve good data while still warning the user that nothing changed. The article’s central point is not that cancellation should be invisible; it is that cancellation should be non-destructive.
SourcesOpenAI Function calling guide (opens a new tab)OpenAI Structured Outputs guide (opens a new tab)
What the tests prove and do not prove
The supplied tests check three outcomes. First, an `ok` result commits a merged state and reports `meta.kind: 'ok'`. Second, a cancelled result preserves the prior state, sets `commit: false`, and reports `meta.kind: 'cancelled'` with the reason preserved. Third, an error result also skips commit, but it is marked as `error` and carries the error payload forward. Those assertions are enough to prove that cancellation and error are not collapsed into the same UI behavior.
The tests also leave an important boundary visible: they do not prove deep immutability, because the implementation uses a shallow merge for `ok`. They do not prove that the same reducer works for nested stores, normalized caches, or framework-specific state containers. They do not prove actual browser rendering or interaction timing. They only prove the decision that should happen when a tool result reaches the UI policy layer.
That limited scope is appropriate for a focused debugging article. A reader who needs a different state shape can swap the merge strategy, but they should keep the policy distinction. Cancellation can preserve the old state, report a non-error outcome, and avoid committing changes. The exact payload shape can vary; the ownership rule should not.
import test from 'node:test'
import assert from 'node:assert/strict'
import { applyToolResult } from './main.mjs'

// Success case: tool returns ok and UI should commit the payload.
test('commits on ok result', () => {
  const prev = { count: 1, name: 'alice' }
  const toolResult = { status: 'ok', payload: { count: 2 } }
  const out = applyToolResult(prev, toolResult)

  assert.equal(out.commit, true)
  // state must be a new object with merged payload
  assert.deepEqual(out.state, { count: 2, name: 'alice' })
  assert.equal(out.meta.kind, 'ok')
})

// Cancellation case: tool returned cancelled -> UI must preserve prior state
// and this should NOT be treated as an error. The meta.kind is 'cancelled'.
test('preserves state on cancelled result (not an error)', () => {
  const prev = { items: ['a'], loading: true }
  const toolResult = { status: 'cancelled', reason: 'user_aborted' }
  const out = applyToolResult(prev, toolResult)

  assert.equal(out.commit, false)
  // state preserved exactly (reference may be same or copied by implementation)
  assert.deepEqual(out.state, prev)
  assert.equal(out.meta.kind, 'cancelled')
  assert.equal(out.meta.reason, 'user_aborted')
})

// Error case: tool failed -> UI should not commit and should mark an error so
// the UI can surface an error state. This contrasts with cancellation above.
test('does not commit and surfaces error on tool error', () => {
  const prev = { value: 10 }
  const toolResult = { status: 'error', error: { code: 502, message: 'bad gateway' } }
  const out = applyToolResult(prev, toolResult)

  assert.equal(out.commit, false)
  assert.deepEqual(out.state, prev)
  assert.equal(out.meta.kind, 'error')
  assert.deepEqual(out.meta.error, { code: 502, message: 'bad gateway' })
})
Where this pattern stops being enough
This pattern is strong when the question is, “Should the UI keep the last good state after a cancelled tool result?” It is weaker when the question becomes, “How should the app recover after a failed request, a stale cache entry, or a partially applied domain mutation?” Those cases need additional mechanisms: request ownership, abort propagation, version checks, or reconciliation logic. Cancellation alone does not solve stale responses, idempotency, or conflicting writes.
The pattern also assumes the application can tell cancellation apart from error at the point where the tool result enters the reducer. If the runtime collapses both into one generic failure object before your code sees them, the UI cannot recover the distinction later. In that situation, the fix belongs in the orchestration layer, not in the render tree. The contract has to preserve the outcome shape all the way to the state transition.
Structured Outputs matter here because they help constrain what the model can emit when you define schemas for tool-adjacent data, but they are not a substitute for UI policy. The docs explicitly note unsupported schema features under strict mode, which is a reminder that schema validation and state ownership solve different problems. The schema helps shape data; the reducer decides what that data is allowed to change.
SourcesOpenAI Structured Outputs guide (opens a new tab)OpenAI Function calling guide (opens a new tab)