How do I choose which prompt prefix to cache versus re-run to cut LLM latency?
Choose which parts of an LLM prompt belong in a reusable prefix, which parts should stay volatile, and how OpenAI's documented caching modes, keys, and lifetimes affect latency and reuse.
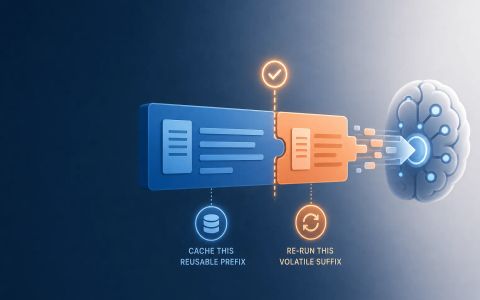
When a prompt gets split into stable instructions and a volatile task suffix, the wrong caching choice can either waste compute or freeze the wrong prefix in place. The provider docs make the mechanics clear: prompt caching reuses a matching prefix, not the whole request, and the reusable prefix has to be long enough to qualify. That means the real job is deciding where the stable region ends.
This article treats that as a design decision instead of a general performance tip. It walks through the documented caching rules, shows how to identify the stable prefix, explains when explicit-only mode and cache keys are useful, and ends with the measurement signals that tell you whether the decision actually improved latency in your application.
What you are deciding when you split a prompt
A prompt-caching decision is not really about whether caching is good. It is about where the reusable boundary should sit when part of the request is stable and part of it changes on every turn. In a multi-part assistant prompt, the stable material is usually the system instructions, developer instructions, tool definitions, and other reference text that the model needs every time. The volatile material is the current task, the new user message, or the latest conversation turn that should not be reused blindly.
That distinction matters because OpenAI's prompt cache reuses the model's saved key-value state for an unchanged prefix. The cache does not store arbitrary tokens for later textual replay; it stores the internal state for the rendered prefix. If the beginning of the next request matches, the model can skip reprocessing those tokens. If the prefix changes before the breakpoint, reuse stops there, even if most of the later prompt looks similar.
The practical question, then, is not 'should I cache everything?' It is 'which prefix is stable enough to pay the cost of caching, and which suffix is too volatile to be worth keeping in that reusable region?' That is the question this article answers with a placement rule, a measurement rule, and a fallback rule.
export function simpleTokenEstimate(text) {
  if (!text) return 0;
  // Very small, deterministic estimator: split on whitespace and punctuation groups.
  // This is intentionally conservative and inexpensive; real apps should use a tokenizer
  // matching the actual model.
  return String(text)
    .trim()
    .split(/\s+|(?=[.,;:!?()\[\]{}"'])|(?<=[.,;:!?()\[\]{}"'])/)
    .filter(Boolean).length;
}

export function analyzePromptParts(parts, { model = 'gpt-5.6', minCacheableTokens = 64 } = {}) {
  // parts: array of { role: 'system'|'developer'|'user'|'assistant', text: string, stable?: boolean }
  // Determine the longest leading contiguous stable prefix (from start) that can be cached.
  if (!Array.isArray(parts)) throw new TypeError('parts must be an array');

  let prefixParts = [];
  let prefixTokenCount = 0;
  for (const p of parts) {
    if (!p || typeof p.text !== 'string') throw new TypeError('each part must have a text string');
    const isStable = Boolean(p.stable);
    if (!isStable) break; // only contiguous leading stable parts are cacheable as one prefix
    prefixParts.push(p);
    prefixTokenCount += simpleTokenEstimate(p.text);
  }

  const prefixText = prefixParts.map(p => p.text).join('\n');
  const isCacheable = prefixTokenCount >= minCacheableTokens;

  // Model-specific guidance: on gpt-5.6+, explicit-only is recommended when suffixes are volatile.
  const major = String(model).toLowerCase();
  const prefersExplicit = major.includes('gpt-5.6') || major.includes('gpt-6') || major.includes('gpt-5.');

  // Suggest cache mode: if there are trailing stable parts later (non-leading), explicit is safer.
  const hasLaterStable = parts.slice(prefixParts.length).some(p => p.stable);
  const suggestedMode = (!isCacheable || hasLaterStable) ? 'explicit' : (prefersExplicit ? 'implicit' : 'explicit');

  const contiguousLeadingStableCount = prefixParts.length;

  return {
    prefixText,
    prefixTokenCount,
    isCacheable,
    minCacheableTokens,
    suggestedMode,
    // top-level convenience for tests and callers
    contiguousLeadingStableCount,
    reason: {
      contiguousLeadingStableCount,
      hasLaterStable,
      model,
    }
  };
}

export function chooseCacheKey(baseKey, { scope = 'global', id = null } = {}) {
  // Simple helper to build a cache-accounting key. Do not include secrets here.
  if (typeof baseKey !== 'string') throw new TypeError('baseKey must be a string');
  const safeScope = String(scope).replace(/[^a-z0-9_:-]/gi, '_');
  if (id == null) return `${safeScope}:${baseKey}`;
  return `${safeScope}:${id}:${baseKey}`;
}

export default { simpleTokenEstimate, analyzePromptParts, chooseCacheKey };SourcesOpenAI Prompt caching (opens a new tab)OpenAI Latency optimization (opens a new tab)
Start with the documented mechanics, not intuition
The documented rule is prefix matching: a later request can reuse cache state only when it has the same rendered prefix and can find an eligible matching breakpoint. That rendered prefix includes OpenAI-provided instructions, developer messages, tool definitions, and conversation history, so changes anywhere in that early portion can invalidate reuse. The cache is therefore not just a feature you turn on once; it is a contract about which early tokens remain identical across requests.
The second rule is that each prefix you want to cache must meet the model's minimum cacheable length. That requirement prevents tiny prefixes from being treated as worthwhile cache entries. For a decision process, this means a prefix is only interesting if it is both stable and long enough to matter. A short, perfectly stable instruction block may still be too small to justify special treatment, especially if your application rarely repeats it.
The third rule is model and mode behavior. On GPT-5.6 and later, the docs distinguish implicit caching from explicit-only caching. Implicit caching places a breakpoint automatically at the end of the latest eligible message. Explicit-only mode lets you place breakpoints deliberately, which becomes important when the suffix changes often and you do not want it to incur cache-write cost. The same guide also documents cache TTL choices, including 30m and 12h minimum lifetimes, and notes that cache keys can be used to separate accounting or routing for customers, users, or workspaces.
Find the stable prefix by asking what changes every turn
The easiest way to pick a caching boundary is to classify each piece of the prompt by volatility. System instructions are usually stable. Tool descriptions and schemas are often stable until you change a tool contract. Conversation history is stable only up to the point where you append new turns. A current task prefix may be partly stable if you have a reusable rubric, but the live user request at the end is usually volatile.
The prompt in this article's example code makes that distinction explicit through a contiguous leading stable region. It marks the system message, developer instructions, and shared examples as stable, then stops at the first volatile user message. That is a useful model even when your real application is more complicated, because it mirrors how cache reuse works: only the unchanged beginning of the rendered prompt can be reused as one prefix. A stable block later in the prompt does not help unless the earlier content stays identical as well.
The decision should be based on content ownership, not on vibes. If a section changes when the user changes, it belongs after the breakpoint. If a section changes when you update a tool schema, it may belong in the cached region only if you are prepared for that update to invalidate the prefix. If a section is expensive to regenerate but rarely changes, it is a strong cache candidate. If a section changes every request, caching it is often a false economy because it converts a volatile suffix into a cache boundary that cannot be reused reliably.
SourcesOpenAI Prompt caching (opens a new tab)OpenAI Latency optimization (opens a new tab)
Measure the prefix before you decide it is worth caching
A good caching decision starts with the size of the candidate prefix. The example helper in this article estimates token cost for each prompt part, totals the contiguous stable prefix, and compares that total with a minimum cacheable threshold. That is not the same as the provider's tokenizer, but it is enough to make the placement decision visible in a local fixture: you can see whether the stable block is likely to be large enough to matter before you build more elaborate instrumentation.
That measurement matters because the latency guide is clear that reducing input tokens usually has a much smaller effect than reducing output tokens, while prompt caching is about avoiding repeated processing of unchanged input. Those are related but different levers. If your stable prefix is tiny, the likely win from caching may be small. If your prefix is large and repeated across many calls, the same rule becomes much more attractive because the model can reuse the prefix state rather than reprocessing it each time.
The article's example also surfaces a practical boundary: a stable prefix below the minimum cacheable length should not be treated as cacheable in your decision flow, even if it feels logically reusable. That is an important negative case because it prevents teams from assuming that every reusable-looking block deserves its own cache plan. The right conclusion may be to shorten the prefix, merge adjacent reusable instructions, or move some instructions into a different layer of the application rather than trying to cache a block that is too short to qualify.
Use keys and lifetimes to keep conversation reuse from leaking into task volatility
OpenAI's docs make two related controls available on GPT-5.6 and later: prompt cache mode and prompt cache key. Mode controls whether breakpoints are implicit or explicit-only. The key controls how cache accounting is separated across customers, users, workspaces, or other application scopes. That second control is not just a billing detail. It also helps keep repeated prefixes from different scopes from collapsing into one accounting bucket when your application needs to reason about reuse per tenant or per session.
This is where the article's example recommendation of separate keys for conversation history and volatile task parameters becomes useful. If you are processing a long-lived support thread, you may want the shared policy or rubric to remain on one stable key while per-user or per-session content gets its own key or its own uncached suffix. The point is not to invent artificial complexity; it is to keep the cache boundary aligned with the part of the prompt that should truly be shared. A different user, customer, or workspace should not inherit cache accounting just because the text looks similar.
The TTL choice also matters. The docs describe 30m and 12h minimum lifetimes, with 12h intended for stable instructions or reference material reused over longer gaps. The key point is that the TTL sets a minimum cache lifetime, not a guaranteed delete time. In practice, that means you choose a longer lifetime only when the prefix is likely to be reused enough to justify it. If the content changes frequently, a shorter lifetime can be the safer default. If the content is reference material or a hot prefix that many requests will reuse, the longer minimum lifetime is often a better fit.
SourcesOpenAI Prompt caching (opens a new tab)OpenAI Latency optimization (opens a new tab)
Plan the fallback before you depend on a cache hit
A cache strategy needs a miss path. When the prefix does not match, or the request changes before the breakpoint, the model must still answer correctly at uncached input rates. The latency docs are useful here because they remind you that fewer requests, fewer output tokens, and smaller model work can all reduce user-visible delay even when caching does not help. Prompt caching should be one tool in the plan, not the only tool.
A practical fallback is to reduce what the model must reason about when reuse fails. If a cache miss occurs on a known hot prefix, you can shorten the prompt by trimming redundant instructions, removing unneeded history, or reducing output verbosity. The latency guide explicitly recommends maximizing the shared prompt prefix by moving dynamic material later in the prompt. If you cannot reuse the prefix, the next best improvement is to shrink the volatile work that remains.
That also explains two common gotchas from the docs. First, append-only updates can prevent reuse if they change the prefix before the breakpoint, because matching depends on the rendered prefix staying identical. Second, compaction can replace earlier conversation content with a compacted context, which may prevent reuse from the first changed token onward. Those are not bugs in the cache; they are reminders that prompt caching is sensitive to prompt shape. If you change the shape often, you should expect reuse to drop and design your application so that a miss still produces an acceptable latency budget and a correct answer.
SourcesOpenAI Prompt caching (opens a new tab)OpenAI Latency optimization (opens a new tab)
Read the example as a decision tool, not as a performance promise
The example implementation in this article is intentionally small: it finds the longest contiguous leading stable prefix, estimates its token cost, and proposes a cache mode based on whether the prefix is long enough and whether later stable parts make explicit-only safer. That is enough to support the article's decision flow, but it does not claim to simulate the provider's internal cache or to prove a real latency reduction by itself. It is a planning helper, not an execution harness.
That distinction is important because the outcomes you ultimately care about are measured on the real system: reduction in model prefix compute time, observed latency drop, and cache hit rate. The provider docs tell you what the cache does and what controls exist; your application metrics tell you whether the prefix you chose actually pays off. A good instrumentation plan counts the repeated prefix length, the rate of cache reuse, and the latency difference between cold and warm requests under the same user-visible workload.
The example also helps you see what the tests can and cannot prove. They can prove that a stable prefix above a threshold is classified as cacheable, that a short prefix is not, and that invalid input is rejected. They cannot prove provider-level reuse, retained cache duration beyond the documented minimum, or real model latency on a production network. The useful conclusion is therefore a decision rule: keep stable instructions and reference material in a reusable prefix, keep volatile task parameters and per-turn text outside that prefix, choose explicit-only when you want precise control over breakpoints, and verify the result with your own latency and hit-rate measurements.
import test from 'node:test';
import assert from 'node:assert/strict';
import { simpleTokenEstimate, analyzePromptParts, chooseCacheKey } from './main.mjs';

// Success case: a multi-part prompt with a large stable prefix that exceeds the minCacheableTokens.
test('success: identifies cacheable leading stable prefix and suggests implicit for modern model', () => {
  const parts = [
    { role: 'system', text: 'You are an assistant. Use formal tone.', stable: true },
    { role: 'developer', text: 'Tool: calculator schema: {...}', stable: true },
    { role: 'developer', text: 'Shared examples:\n1) Q -> A\n2) Q2 -> A2', stable: true },
    // user content is a volatile suffix
    { role: 'user', text: 'User question: What is 2+2?', stable: false }
  ];

  const analysis = analyzePromptParts(parts, { model: 'gpt-5.6', minCacheableTokens: 5 });

  // The three leading parts should be treated as the prefix
  assert(analysis.contiguousLeadingStableCount !== undefined || analysis.reason.contiguousLeadingStableCount === undefined, 'analysis includes counts');
  assert(analysis.prefixTokenCount >= 5, 'prefix token count meets the small min');
  assert(analysis.isCacheable === true, 'prefix is cacheable');
  // For gpt-5.6 the helper marks that explicit-only is available but when contiguous prefix is whole stable block and no later stable it can be implicit
  assert(analysis.suggestedMode === 'implicit' || analysis.suggestedMode === 'explicit', 'suggestedMode is one of allowed strings');
});

// Boundary / failure case: prefix is too short to meet minimum cacheable tokens
test('failure/boundary: short stable prefix is not cacheable', () => {
  const parts = [
    { role: 'system', text: 'Short instr.', stable: true },
    { role: 'user', text: 'Volatile user input', stable: false }
  ];

  const analysis = analyzePromptParts(parts, { model: 'gpt-5.6', minCacheableTokens: 100 });
  assert.strictEqual(analysis.isCacheable, false, 'prefix below threshold must not be marked cacheable');
  assert(analysis.prefixTokenCount < 100, 'prefix token count is below the configured minimum');
  assert.strictEqual(analysis.suggestedMode, 'explicit', 'explicit mode is safer when not cacheable or later stable parts exist');
});

// Failure case: invalid inputs must throw useful errors; tests ensure API surface is validated
test('failure: invalid parts input throws TypeError', () => {
  assert.throws(() => analyzePromptParts(null), TypeError);
  assert.throws(() => analyzePromptParts([ { text: 123 } ]), TypeError);
  assert.throws(() => chooseCacheKey(123), TypeError);
});

// Additional small tests to exercise token estimator and key building (not counted as one of the main tests)
test('token estimator and cache key builder behave deterministically', () => {
  const tokens = simpleTokenEstimate('Hello, world! This is a test.');
  assert.strictEqual(typeof tokens, 'number');
  assert(tokens > 0);

  const k1 = chooseCacheKey('shared_prefix', { scope: 'customer', id: 'cust_42' });
  const k2 = chooseCacheKey('shared_prefix', { scope: 'customer', id: 'cust_42' });
  assert.strictEqual(k1, k2);
});
SourcesOpenAI Prompt caching (opens a new tab)OpenAI Latency optimization (opens a new tab)