AI
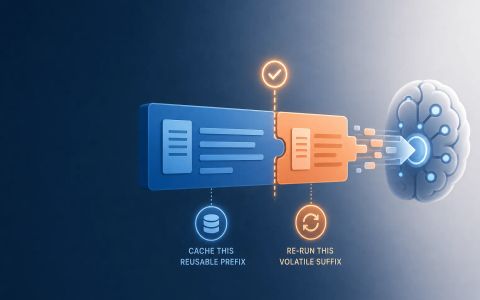
How do I choose which prompt prefix to cache versus re-run to cut LLM latency?
Choose which parts of an LLM prompt belong in a reusable prefix, which parts should stay volatile, and how OpenAI's documented caching modes, keys, and lifetimes affect latency and reuse.
About 14 min read